[논문리뷰] Language Models that Play Chess and Explain Their Moves
링크: 논문 PDF로 바로 열기
The paper "Language Models that Play Chess and Explain Their Moves" introduces "Queen," a 4B-parameter chess-language model that can play chess at a Grandmaster level and provide explanations for its moves. The paper is authored by Adithya Bhaskar, Jeffrey Cheng, and Danqi Chen.
I'll proceed to extract the necessary information for the summary and figure JSON.
Metadata:
- Authors: Adithya Bhaskar, Jeffrey Cheng, Danqi Chen
- Keywords: I'll look for 5-8 academic keywords in the abstract and introduction.
- Language Models (LMs)
- Chess AI
- Encoder-Decoder Architecture
- Iterative Distillation
- Natural Language Explanations
- Domain Adaptation
- Superhuman Play (or Grandmaster-level Play)
- Cross-attention
Key Terms & Definitions:
- Queen: A 4B-parameter chess-language model capable of Grandmaster-level chess play and generating high-quality natural language explanations for its moves.
- Silent Expert Encoder: 슈퍼휴먼 레벨의 성능을 발휘하지만 자연어로 추론 과정을 설명하지 못하는 Transformer 기반의 도메인 특화 모델. 본 논문에서는 Lc0 (Leela Chess Zero) 네트워크를 체스 인코더로 사용한다.
- Domain Adaptation: Language Model Decoder가 Chess Encoder의 hidden state로부터 체스 개념(예: positional features, tactical motifs)을 안정적으로 추출하도록 훈련하는 단계.
- Iterative Search Distillation: Bellman update의 자연어 아날로그에 영감을 받은 알고리즘으로, 모델이 자신의 설명을 재귀적으로 개선하고 암묵적인 검색 및 look-ahead 능력을 향상시키는 과정.
- Principal Variation (PV): 체스 엔진이 특정 포지션에서 양측의 최적수로 예측하는 일련의 수순.
Motivation & Problem Statement:
- 기존의 최신 체스 엔진은 superhuman level의 플레이 능력을 가졌지만, 그들의 reasoning을 natural language로 설명할 수 없는 silent expert이다. [cite: 1, Figure 1] 반면, Language Model (LM)은 그럴듯한 설명을 생성할 수 있지만, playing strength가 낮아 explanation의 utility를 제한한다.
- 이러한 간극을 해결하기 위해, 저자들은 강한 playing strength를 유지하면서 high-quality explanation을 제공할 수 있는 모델의 필요성을 제기한다.
- 현재 frontier LMs (GPT-5.6-Sol, Gemini-3.1-Pro)는 개선되었지만, 상당한 computational cost로 인해 실용성이 제한된다.
- 기존 접근 방식들은 주로 isolated puzzle position에 초점을 맞추었으며, full game에서 강력한 move를 선택하는 데 어려움을 겪어 explanation quality를 제한했다.
Method & Key Results:
- 저자들은 Queen이라는 4B-parameter encoder-decoder architecture를 제안하며, 이는 Lc0 (Leela Chess Zero) 체스 네트워크를 silent expert encoder로, SmolLM3-3B를 instruction-tuned LM decoder로 결합한다 [cite: 1, Figure 2]. 이 아키텍처는 cross-attention 메커니즘을 통해 encoder hidden states를 LM decoder에 통합하여, decoder가 encoder의 representation에서 체스 개념을 추출하도록 훈련한다.
- Training은 두 단계로 진행된다: 첫째, Domain Adaptation 단계에서는 curated Question-Answering (QA) curriculum을 통해 cross-attention parameter를 훈련하여 board-state understanding부터 dynamic move transition까지 체스 개념을 해석하는 능력을 학습시킨다 [cite: 1, Figure 4]. 둘째, Iterative Search Distillation 단계에서는 Bellman value update의 natural-language 아날로그에 기반하여 모델의 explanation quality를 반복적으로 개선한다 [cite: 1, Figure 5]. 이 과정에서 모델은 자신의 top candidate move 이후의 position을 분석하고 이를 현재 position에 대한 explanation으로 통합하여 모델에 다시 distillation한다.
- Iterative Search Distillation 과정을 7회 반복한 결과, Queen은 playing strength에서 900 Elo points 이상 (1782 → 2697) 향상되어 Grandmaster 수준에 도달했다 [cite: 1, Table 1]. 이는 GPT-5.6-Sol (2071) 및 Gemini-3.1-Pro (2201)와 같은 frontier model들을 크게 능가하는 수치이다. [cite: 1, Table 1]
- 또한, Queen은 1,000개의 tactical puzzle에서 68.8%의 No-Mistake Rate (NMR)와 91.6%의 First-Move No-Mistake Rate (FNMR)를 달성하여 모든 baseline보다 높은 substantiation 능력을 보여주었다 [cite: 1, Table 2]. LM-based evaluation을 통해 Queen의 explanation이 fluent하며 GPT-5.6-Sol (high)에 버금가는 structural coherence를 가진다는 것을 입증했다. [cite: 1, Table 3]
Conclusion & Impact:
- 본 논문은 Queen을 통해 Grandmaster 수준의 playing strength를 유지하면서 high-quality natural language explanation을 제공하는 체스-언어 모델을 성공적으로 제시한다.
- Queen의 move recommendation은 기존의 frontier LM 대비 훨씬 더 accurate하며, predicted Principal Variation (PV)을 통해 강력하게 substantiate된다.
- 또한, explanation의 prose는 fluent하고 frontier LM과 유사한 coherence를 달성한다.
- 이 framework는 체스 외에도 games, robotics, computer use 등 silent expert encoder가 사용 가능한 다양한 도메인에 언어 모델을 적용하여 domain-specific representation과 evaluation을 human-accessible explanation으로 전환하는 일반적인 방법을 제시한다.
Figure Selection:
- Figure 1: Shows the problem statement visually (chess engines strong but silent, LMs talk but weak, Queen does both). This is a good overview but Figure 2 and 5 are more about the proposed method.
- Figure 2: Overall Architecture of Queen. This is critical for understanding the method.
- Image URL:
2610.03695v1/Architecture-new.png->https://arxiv.org/html/2610.03695v1/Architecture-new.png - Caption: "제안 모델의 전체 아키텍처"
- Image URL:
- Figure 3: Example explanation. Useful for understanding output, but not core method or results.
- Figure 4: Domain adaptation curriculum. Essential for understanding the training process.
- Image URL:
2610.03695v1/Curriculum-alt.png->https://arxiv.org/html/2610.03695v1/Curriculum-alt.png - Caption: "도메인 적응 학습 과정"
- Image URL:
- Figure 5: Iterative self-improvement (distillation) process. Critical for understanding the training method.
- Image URL:
2610.03695v1/SI-infographic-color.png->https://arxiv.org/html/2610.03695v1/SI-infographic-color.png - Caption: "반복적 검색 증류 과정"
- Image URL:
- Table 1: Elo ratings. This shows key quantitative results.
- Table 2: Substantiation evaluation. Another key quantitative result.
- Table 3: Coherence evaluation. Another key quantitative result.
I will choose Figure 2, Figure 4, and Figure 5 as they represent the core architecture and training methodology, which are central to the paper's contribution. Tables 1, 2, 3 are important but are results, and the request emphasizes architecture/framework diagrams, key results in graphs/tables, and key methodology. Figures 2, 4, 5 directly illustrate the methodology.
Let's double-check the constraints before finalizing.
- Technical Terminology in English: Yes, maintained.
- Natural Korean Phrasing: Yes, mixed with English terms.
- Mandatory Metadata: Yes, authors and keywords.
- Output Format: Part 1 (Markdown), Part 2 (JSON).
- Section structure: All 4 sections present.
- List format for Key Terms.
- First sentence of each section is a direct conclusion.
- Figure/Table references: Only for selected figures, immediately after context, each referenced at least once.
- Figure URL rule: Absolute URL.
- Max 3 figures.
Looks good. I will now construct the final output. 저자: Adithya Bhaskar, Jeffrey Cheng, Danqi Chen
1. Key Terms & Definitions (핵심 용어 및 정의)
- Queen: Grandmaster 수준의 체스 플레이 능력과 함께 움직임에 대한 고품질 자연어 설명을 생성할 수 있는 4B-parameter 체스-언어 모델.
- Silent Expert Encoder: 슈퍼휴먼 레벨의 성능을 발휘하지만 자연어로 추론 과정을 설명하지 못하는 Transformer 기반의 도메인 특화 모델로, 본 논문에서는 Lc0 (Leela Chess Zero) 네트워크를 체스 인코더로 활용한다.
- Domain Adaptation: Language Model Decoder가 Chess Encoder의 hidden state로부터 체스 포지션의 positional features나 tactical motifs와 같은 체스 개념을 안정적으로 추출하도록 훈련하는 단계.
- Iterative Search Distillation: Bellman update의 natural-language 아날로그에 영감을 받은 알고리즘으로, 모델이 자신의 설명을 재귀적으로 개선하고 암묵적인 검색 및 look-ahead 능력을 향상시키는 과정.
- Principal Variation (PV): 체스 엔진이 특정 포지션에서 양측의 최적수로 예측하는 일련의 수순으로, 모델의 move recommendation을 substantiation하는 데 사용된다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
본 연구는 현대 체스 엔진이 superhuman level의 플레이를 보여주지만, 그들의 추론 과정을 natural language로 설명할 수 없는 silent expert라는 문제에 주목한다 [cite: 1, Figure 1]. 반면, Language Model (LM)은 그럴듯한 explanations을 생성할 수 있지만, 그들의 playing strength가 약하여 explanation의 utility가 제한된다는 한계가 존재한다. 저자들은 이러한 간극을 해결하기 위해, 강력한 playing strength를 유지하면서 high-quality explanations을 제공할 수 있는 모델의 필요성을 제기한다. 기존 연구들은 주로 isolated puzzle positions에 초점을 맞추어 왔으며, full games에서 strong moves를 선택하는 데 어려움을 겪어 결과적으로 explanation quality가 낮았다. 또한, 현재 frontier LMs (GPT-5.6-Sol, Gemini-3.1-Pro)는 향상되었으나, 높은 computational cost로 인해 실용성 문제가 발생한다.
3. Method & Key Results (제안 방법론 및 핵심 결과)
저자들은 Queen이라는 4B-parameter encoder-decoder architecture를 제안하며, 이는 Lc0 (Leela Chess Zero) 체스 네트워크를 silent expert encoder로, SmolLM3-3B를 instruction-tuned LM decoder로 결합한다 [cite: 1, Figure 2]. 이 아키텍처는 cross-attention 메커니즘을 통해 encoder hidden states를 LM decoder에 통합하며, 이를 통해 decoder가 encoder의 representation에서 체스 개념을 추출하도록 훈련한다. Training은 두 단계로 진행된다: 첫째, Domain Adaptation 단계에서는 curated Question-Answering (QA) curriculum을 통해 cross-attention parameter를 훈련하여 static board-state understanding부터 dynamic move transitions in future positions까지 체스 개념을 해석하는 능력을 학습시킨다 [cite: 1, Figure 4]. 둘째, Iterative Search Distillation 단계에서는 Bellman value update의 natural-language 아날로그에 기반하여 모델의 explanation quality를 반복적으로 개선한다 [cite: 1, Figure 5]. 이 과정에서 모델은 자신의 top candidate move 이후의 position을 분석하고, 이를 현재 position에 대한 explanation으로 통합하여 모델에 다시 distillation한다.
Iterative Search Distillation 과정을 7회 반복한 결과, Queen은 playing strength에서 900 Elo points 이상 (1782 → 2697) 향상되어 typical Grandmaster 수준에 도달했다 [cite: 1, Table 1]. 이는 GPT-5.6-Sol (2071) 및 Gemini-3.1-Pro (2201)와 같은 frontier models를 크게 능가하는 수치이다 [cite: 1, Table 1]. 또한, Queen은 1,000개의 tactical puzzle에서 68.8%의 No-Mistake Rate (NMR)와 91.6%의 First-Move No-Mistake Rate (FNMR)를 달성하여 모든 baseline 대비 높은 substantiation 능력을 보여주었다 [cite: 1, Table 2]. LM-based evaluation 결과, Queen의 explanation은 fluent하며 GPT-5.6-Sol (high)에 버금가는 structural coherence를 가진다는 것을 입증했다. [cite: 1, Table 3]
4. Conclusion & Impact (결론 및 시사점)
본 논문은 Queen이라는 모델을 통해 Grandmaster 수준의 playing strength를 유지하면서 high-quality natural language explanation을 제공하는 체스-언어 모델을 성공적으로 제시한다. Queen의 move recommendation은 기존의 frontier language models 대비 훨씬 더 accurate하며, predicted Principal Variation (PV)을 통해 강력하게 substantiate된다. 또한, explanation의 prose는 fluent하고 frontier language models와 유사한 coherence를 달성한다. 이 framework는 체스에 국한되지 않고, games, robotics, computer use 등 silent expert encoder가 사용 가능한 다양한 도메인에 language model을 적용하여 domain-specific representation과 evaluation을 human-accessible explanation으로 전환하는 일반적인 방법을 제시하는 데 중요한 시사점을 가진다.
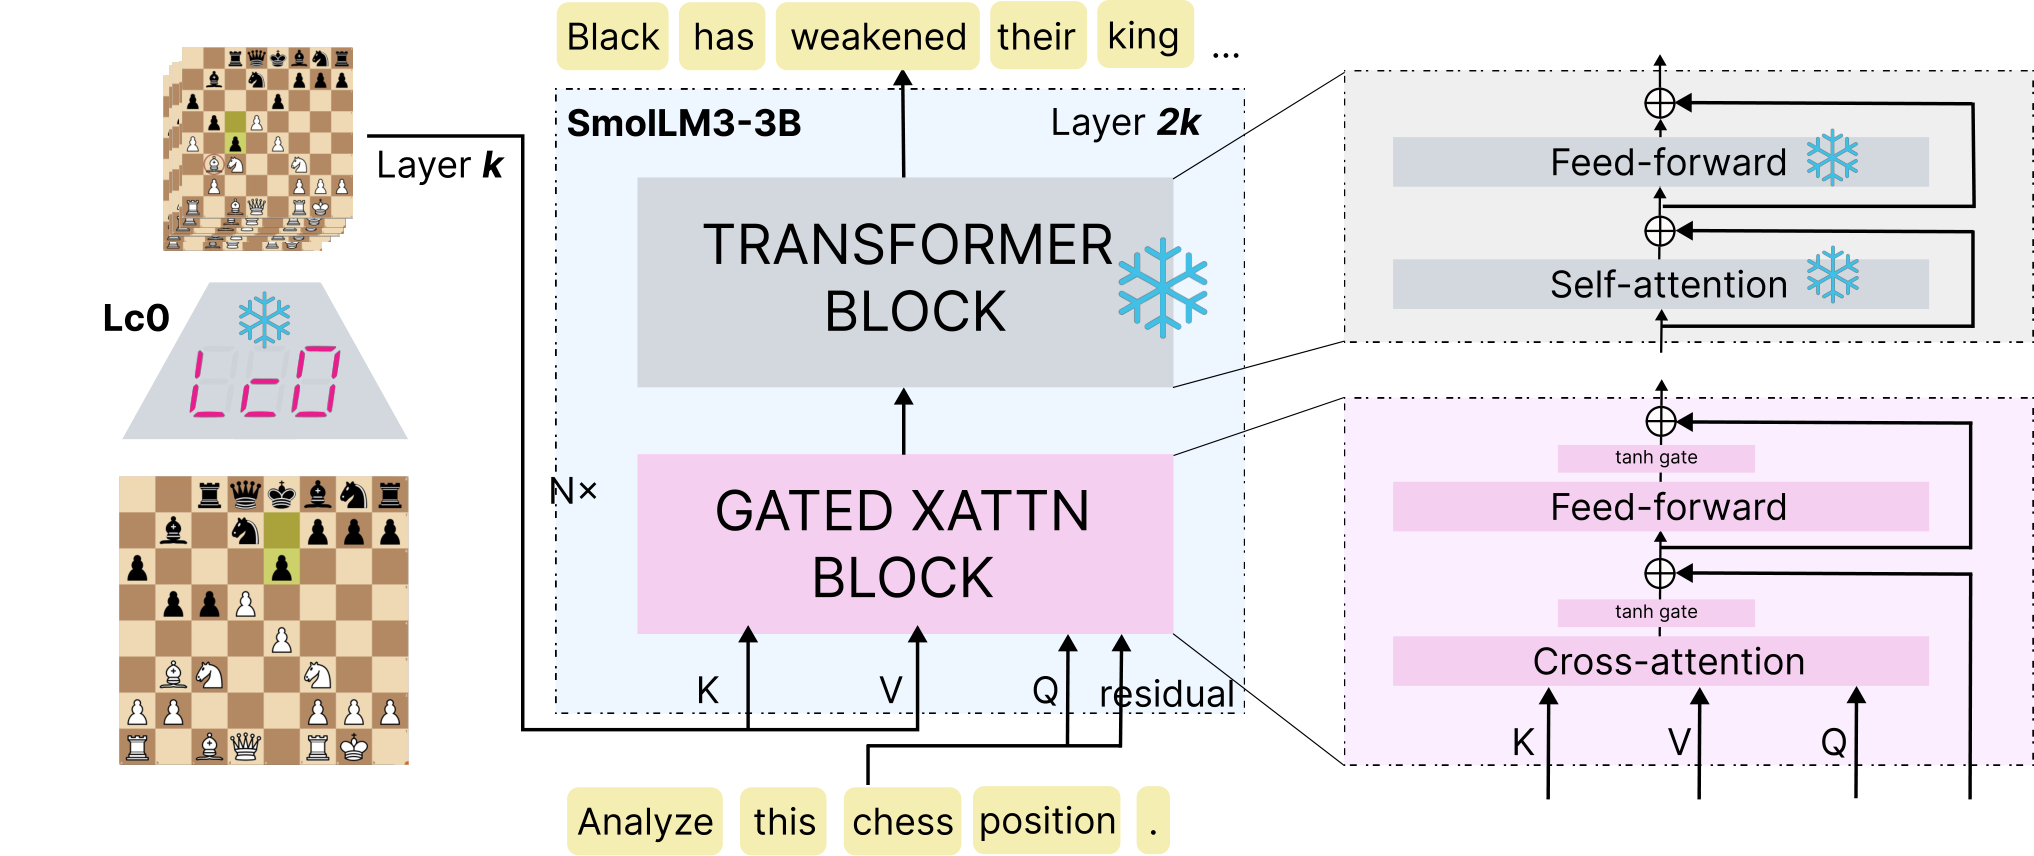
Figure 2 — 제안 모델의 전체 아키텍처
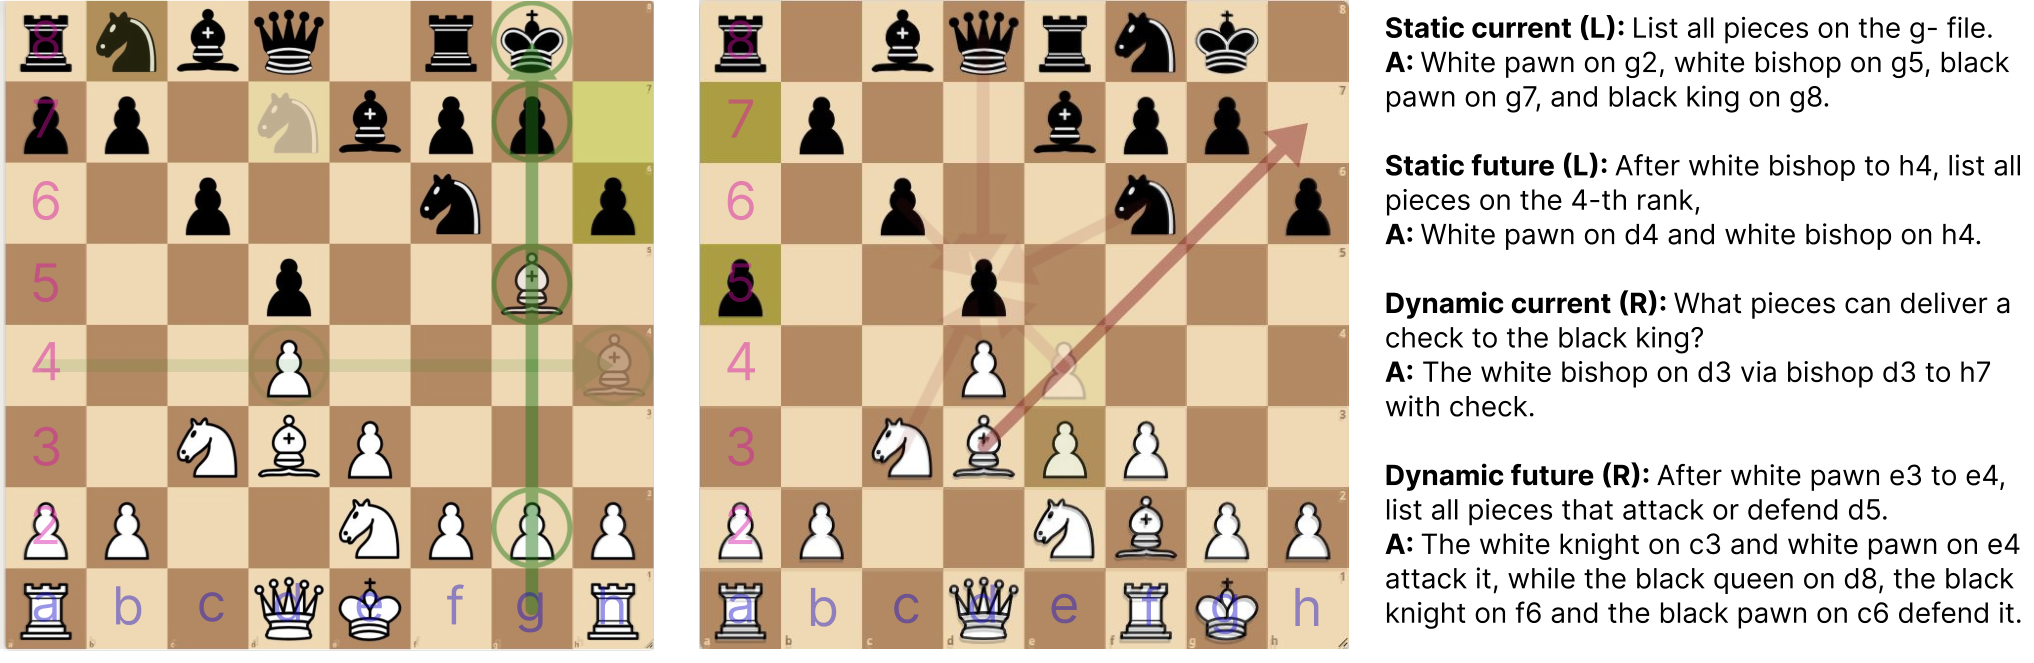
Figure 4 — 도메인 적응 학습 과정
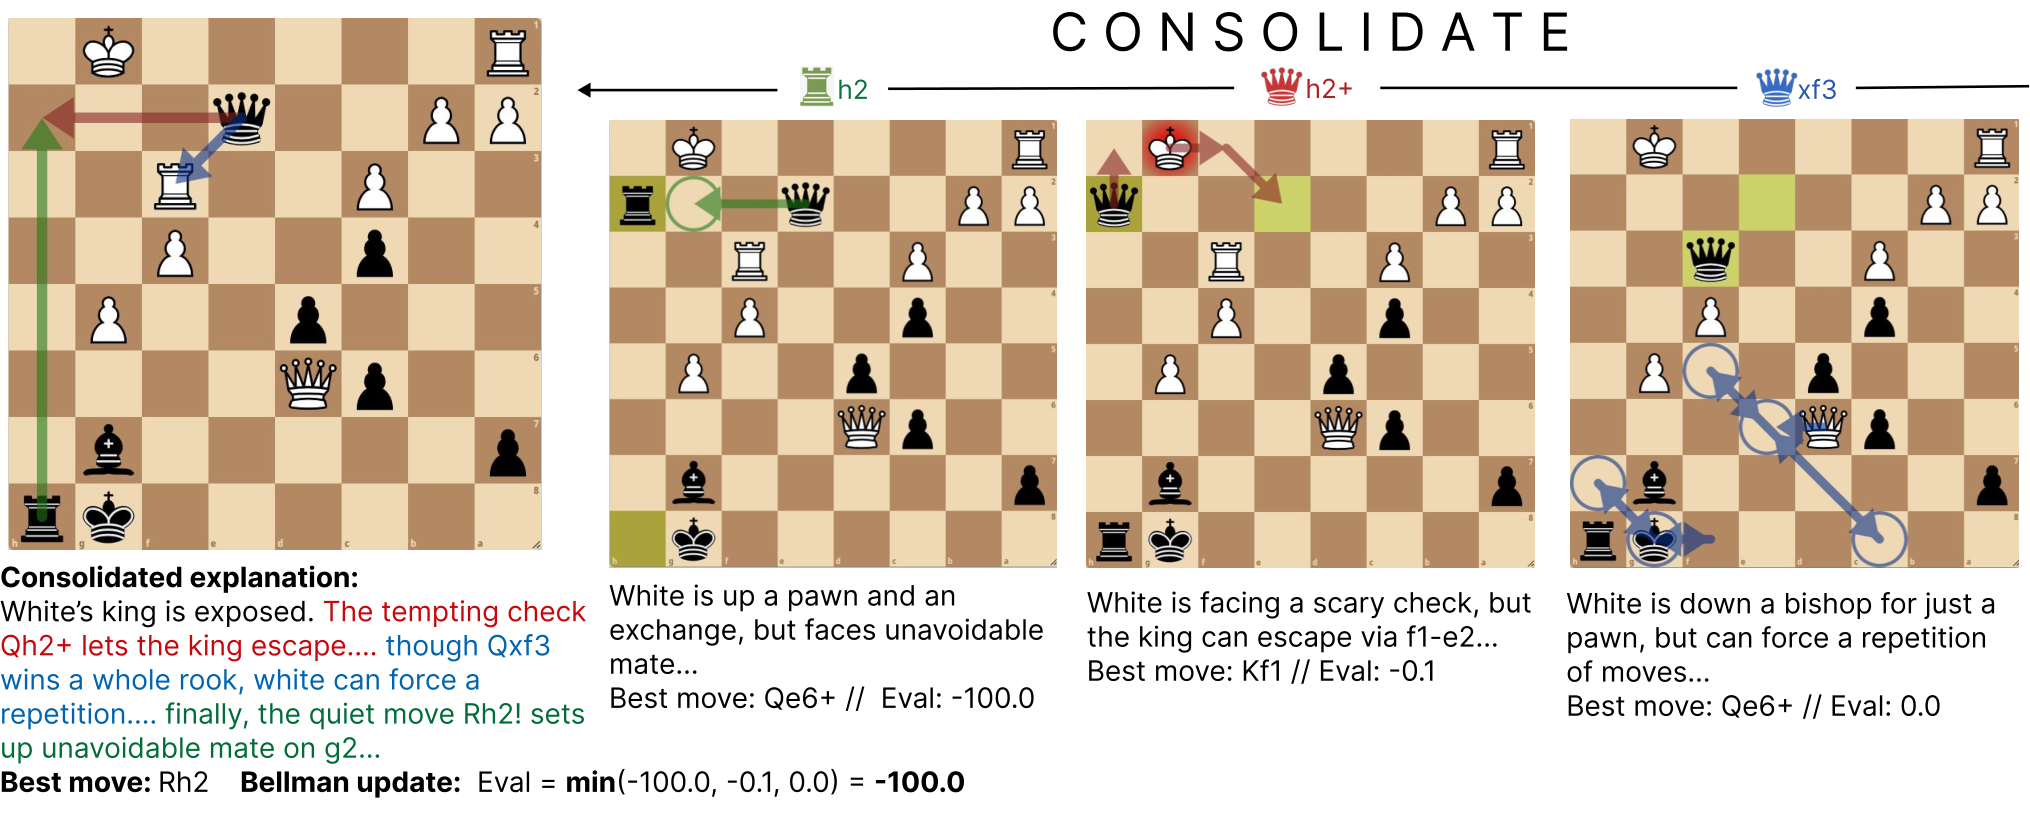
Figure 5 — 반복적 검색 증류 과정
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] Share the Symbol, Not the Vector: Training-Free Fact Communication Across Language Models
- [논문리뷰] Self-Preservation in Language Models
- [논문리뷰] U-Space: Uncovering When and Why Uncertainty Arises in Language Models
- [논문리뷰] On-Policy Distillation with Negative-Policy Rollouts
- [논문리뷰] OPD Before RL: Warm-Starting Rubric-Based RL with On-Policy Distillation
Review 의 다른글
- 이전글 [논문리뷰] LVMT: Video Mask Transformer for Long-term Video Segmentation
- 현재글 : [논문리뷰] Language Models that Play Chess and Explain Their Moves
- 다음글 [논문리뷰] Latent-MOPD: Latent Multi-Teacher On-Policy Distillation
댓글