[논문리뷰] InfoVis: Unified Slide Image Generation and Editing
링크: 논문 PDF로 바로 열기
I have browsed the paper. Now I will proceed with generating the summary and figure information based on the content.
Part 1: Summary
Authors: Jiahao Wang, Xiyan Jiang, Chenyuan Wu, Haoqiang Zhang, Xin Luo, et al.
Keywords: Slide Generation, Slide Editing, Multimodal AI, VisSlideBench, Content Faithfulness, Aesthetic Quality, Instruction Following
1. Key Terms & Definitions (핵심 용어 및 정의)
- InfoVis: 논문에서 제안하는 통합 9B slide generation 및 editing 모델로, text rendering, instruction following, visual grounding, aesthetic design, precise editing 등의 복합적인 능력을 단일 캔버스 내에서 수행한다.
- VisSlideBench: single-slide image generation 및 editing을 위한 새로운 benchmark로, text-to-slide generation, template-conditioned generation, multi-image grounded generation, instruction-based slide editing의 네 가지 slide-centric tasks를 포괄하며, 다차원적인 평가를 제공한다.
- Content Faithfulness (CF): 생성된 슬라이드 이미지에서 요구되는 텍스트 및 시각적 자산이 얼마나 정확하게 보존되고 통합되었는지를 평가하는 지표이다.
- Instruction Following (IF): 생성된 슬라이드 이미지가 주어진 디자인 요구사항(예: 배경, 색상 팔레트, 타이포그래피, 레이아웃)을 얼마나 잘 따랐는지를 측정하는 지표이다.
- Aesthetic Quality (AQ): 슬라이드의 내재적인 시각적 품질, 즉 Clarity, Layout, Style Coherence, Presentation Professionalism을 평가하는 지표이다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
Presentation slides의 생성 및 편집은 정확한 text rendering, instruction following, visual grounding, aesthetic design, precise editing 등 다양한 기능의 통합적 수행을 요구한다. 기존 연구들은 이러한 능력의 일부만을 다루거나, 대규모 slide-native supervision 및 진단적 evaluation이 부족하여, 정확하고 세련되며 제어 가능한 슬라이드 생성 및 편집이 어렵다는 한계가 있었다. 범용 image generators는 광범위한 시각적 분포에 대해 훈련되어 있어, presentation slides의 특징인 content–layout–design relationships에 대한 supervision이 제한적이었다. 또한, 기존 benchmarks는 주로 programmatic 또는 deck-level presentation generation에 초점을 맞추거나, 슬라이드를 더 넓은 시각적 콘텐츠 작업의 하위 집합으로만 포함하여, 단일 슬라이드 이미지 생성 및 편집에 필요한 개별적인 능력을 체계적으로 진단하지 못했다. 이 연구는 이러한 문제점을 해결하고자 unified conditional visual synthesis problem으로 슬라이드 생성을 재정의하고, 네 가지 slide-centric tasks에 대한 데이터 및 benchmark를 구축한다 [Figure 1].
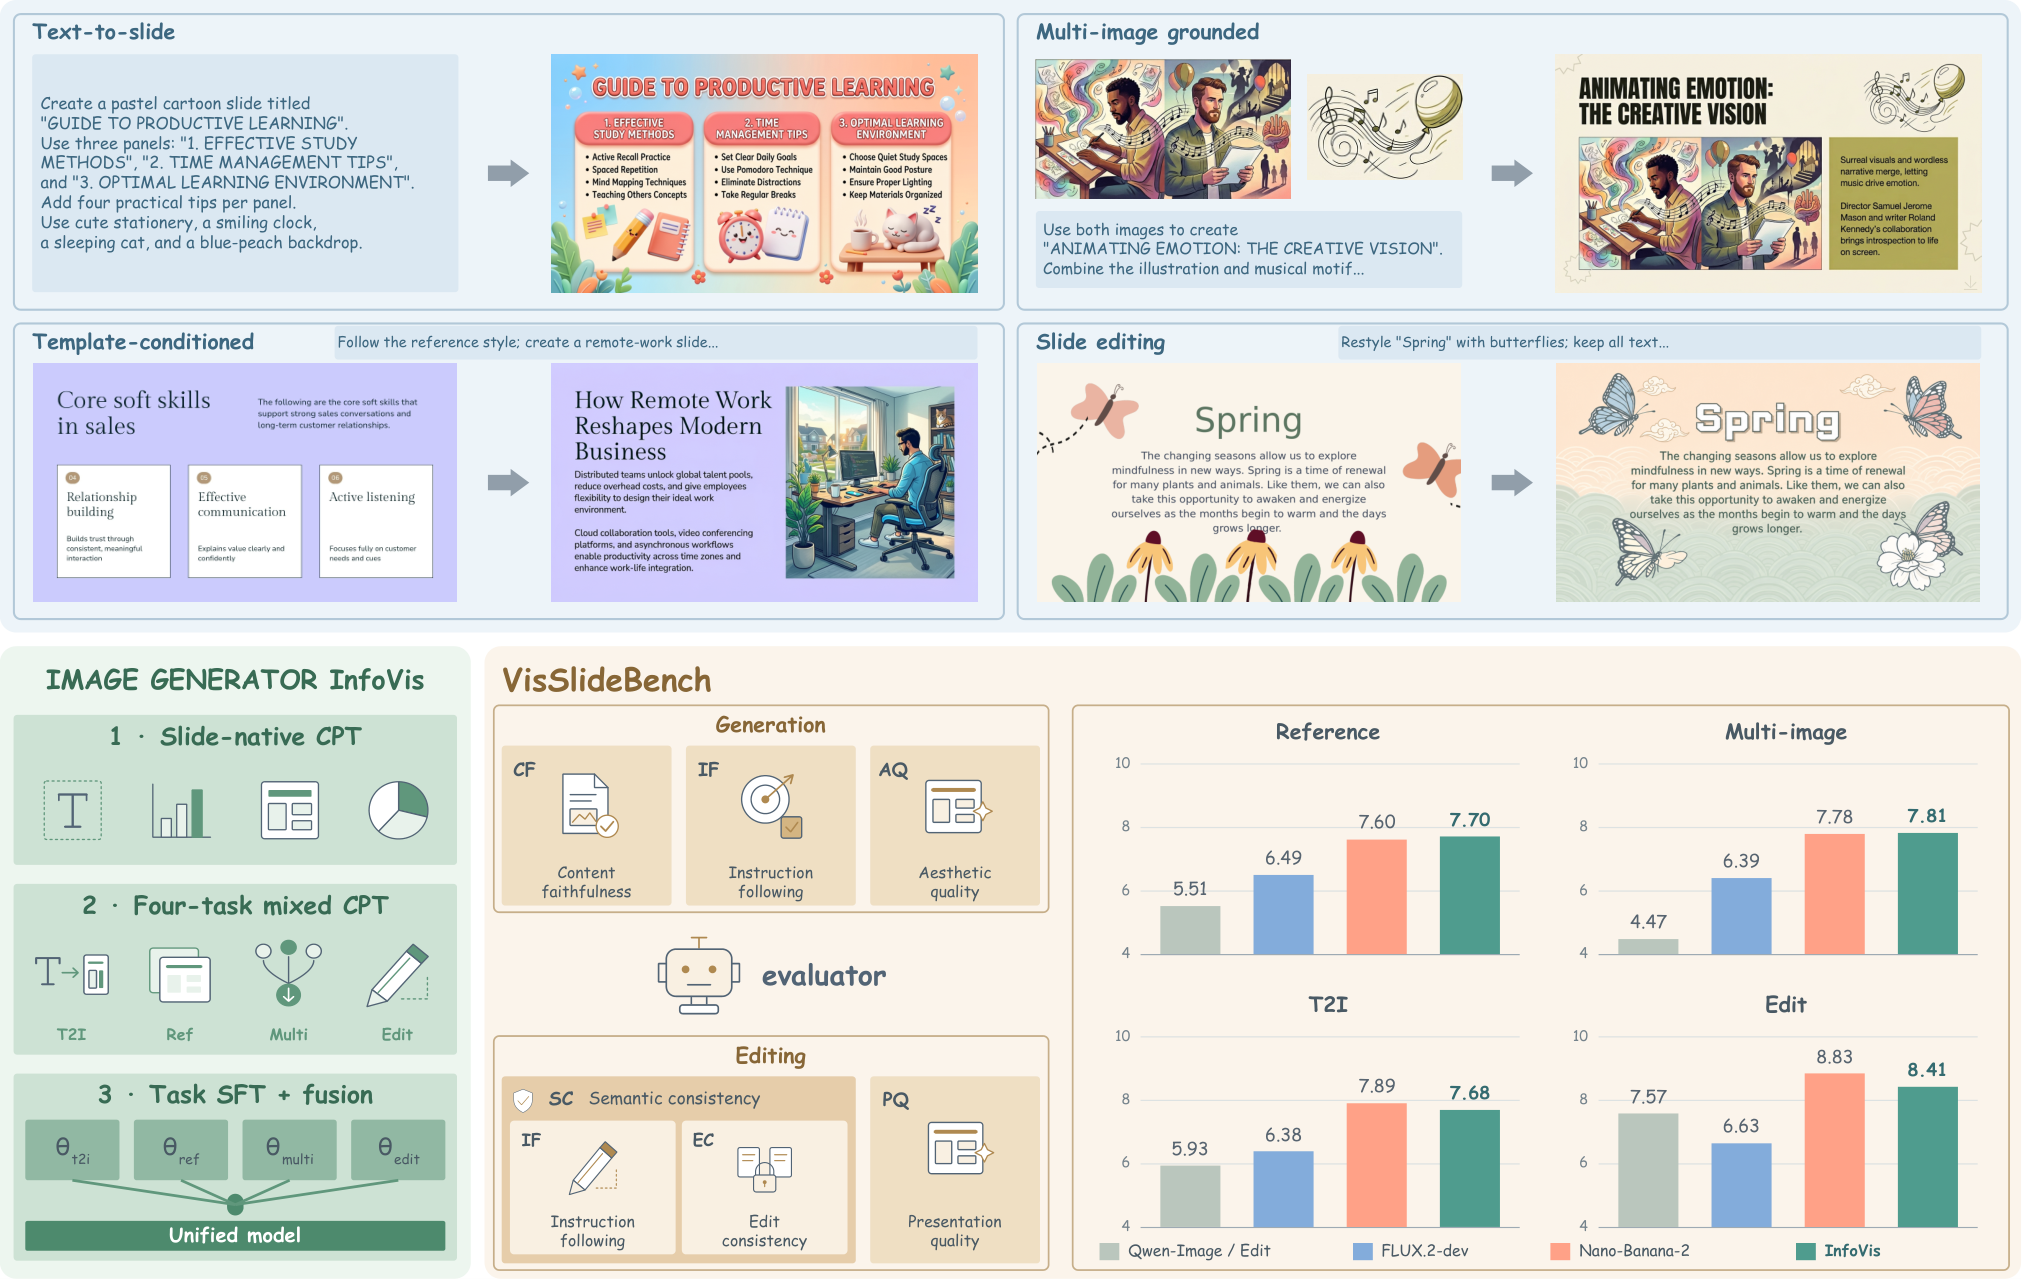
Figure 1 — InfoVis, 작업 및 벤치마크 개요
3. Method & Key Results (제안 방법론 및 핵심 결과)
본 논문은 InfoVis라는 통합 9B slide generation and editing model을 제안하며, FLUX.2-klein-base-9B 모델을 기반으로 세 단계의 slide-native post-training을 거쳐 훈련된다. 첫 번째 단계에서는 대규모 text-to-slide data로 continual pretraining을 수행하여 slide domain에 적응시키고, text rendering, layout, visual hierarchy, design을 공동으로 조정하는 공유 priors를 학습한다. 두 번째 단계에서는 네 가지 작업 데이터셋(text-to-slide generation, template-conditioned generation, multi-image grounded generation, instruction-based slide editing)을 혼합하여 continual pretraining을 진행한다 [Figure 2]. 마지막 단계에서는 task-specific supervised fine-tuning (SFT)을 수행하고, 최종적으로 모델 fusion을 통해 최종 InfoVis 모델을 생성한다.
InfoVis는 VisSlideBench에서 평가된 모든 open-source model들을 11개 metrics 모두에서 능가하며, Nano-Banana-2의 7.99점에 근접한 7.94점의 overall score를 달성했다 [Table 1]. 특히, FLUX.2-klein-base-9B를 기반으로 한 slide-specific post-training을 통해 overall score를 1.64 points 향상시켰으며, Content Faithfulness에서 가장 큰 개선(+1.70 to +2.14 points)을 보였다. 이는 슬라이드 훈련이 밀집된 텍스트 및 제공된 자산의 충실한 렌더링을 주로 개선했음을 시사한다. InfoVis는 Content Faithfulness에서는 GPT-Image-2 및 Nano-Banana-2와 거의 동등하거나 능가하는 성능을 보였고, Instruction Following에서도 유사한 성능을 나타냈으나, Aesthetic Quality에서는 여전히 proprietary models 대비 격차가 존재했다 [Table 1, Table 12, Table 13, Table 14]. 외부 benchmark인 BizGenEval Slides에서는 InfoVis가 open-source models 중 최고의 성능(46.0/79.8)을 기록했으며 [Table 2], SlidesGen-Bench의 Aesthetics evaluation에서는 document-to-slide workflow가 27.09점으로 두 번째로 높은 점수를 달성하여, end-to-end presentation creation에서도 우수한 시각적 품질을 입증했다 [Table 3].
4. Conclusion & Impact (결론 및 시사점)
본 연구는 slide image generation 및 editing을 위한 통합 프레임워크인 InfoVis를 성공적으로 제시한다. 연구팀은 네 가지 상호 보완적인 작업을 정립하고, 대규모 slide-native training resource를 구축했으며, 다차원적 평가를 위한 VisSlideBench를 도입했다. 이러한 자원들을 활용하여 훈련된 InfoVis 모델은 VisSlideBench에서 모든 평가된 open-source model 중 가장 강력한 overall performance를 달성했으며, Nano-Banana-2와 GPT-Image-2와 비교해도 경쟁력 있는 성능을 보였다.
이 연구는 slide-specific supervision이 모델 성능 향상에 결정적인 역할을 함을 입증했으며, unified training이 task specialists에 비해 성능 저하를 거의 일으키지 않으면서도 다양한 슬라이드 관련 작업을 효과적으로 처리할 수 있음을 보여준다. 이는 학계 및 산업계에서 복잡한 시각적 콘텐츠 생성 및 편집을 위한 multimodal AI models 개발에 중요한 기반을 제공할 것이다. 특히, InfoVis를 기반으로 한 document-to-slide workflow는 end-to-end presentation creation에서 최고 수준의 aesthetic quality를 달성하며, 실제 응용 분야에서 프레젠테이션 제작 과정을 자동화하고 효율성을 높이는 데 크게 기여할 수 있는 잠재력을 가진다.
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] LLMs4All: A Review on Large Language Models for Research and Applications in Academic Disciplines
- [논문리뷰] WorldCast: Exploring Intelligent Visual Generation in World State Prediction
- [논문리뷰] Waypoint-OPD: Transferring RL-Induced Policy Shifts via Gated On-Policy Distillation
- [논문리뷰] Virtual Head Attention
- [논문리뷰] VLA-Δ: Learning Physical State Transition for Vision-Language-Action Models
Review 의 다른글
- 이전글 [논문리뷰] InfiniSplat v2: Analyzing and Improving Feed-Forward 3DGS from Any Views
- 현재글 : [논문리뷰] InfoVis: Unified Slide Image Generation and Editing
- 다음글 [논문리뷰] Intern-Decision: Efficient Multimodal Decision Making with Autoregressive Masked Language Modeling
댓글