[논문리뷰] CoWindow Attention: Full Causal Coverage Is a Collective Property
링크: 논문 PDF로 바로 열기
저자: Jingze Shi, Zhangyang Peng, Xianduo Li, Yanlin Qi, Xiaotian Lin, Haoxian Chen, Liangdong Wang, Guang Liu, Yuyu Luo
1. Key Terms & Definitions
본 논문은 CoWindow Attention (CoWA)의 핵심 구성 요소 및 관련 개념을 정의한다.
- CoWindow Attention (CoWA):
KV heads전반에 걸쳐causal history접근을 분산하는structured attention architecture이다. - Full Causal Coverage: 각
attention layer내에서 모든causal token position이KV head앙상블의 최소 한 개 이상에 의해visible함을 보장하는 속성이다. - Collective Coverage:
full causal coverage가 개별attention head마다 전체history를duplicate하는 대신,head ensemble의collective property로 제공될 수 있다는 원칙이다. - Near-diagonal Window:
CoWA에서 모든KV heads가 공유하며,recent context에 대한direct access를 유지하는attention window이다. - Prefix-sink Window:
CoWA에서 모든KV heads가 공유하며,sequence의 시작 부분을visible하게 유지하는attention window이다. - Long-range Window:
CoWA에서 나머지causal distances를partition하여 각KV head에complementary하게 할당되는attention window이다.
2. Motivation & Problem Statement
Long-context full attention (FullAttn)은 IO-efficient dense kernels을 사용함에도 불구하고 상당한 redundant computation 및 memory traffic을 발생시키며, 저자들은 이 문제를 해결하고자 한다. 현재 context length가 thousands에서 hundreds of thousands의 tokens로 확장됨에 따라 FullAttn의 computational burden은 더욱 커지고 있다. 기존 sparse attention 방법론들은 (sliding-window attention, global tokens, fixed block patterns, dynamic approaches) finite horizon을 적용하여 distant tokens에 대한 direct access를 제한하거나, predetermined paths만 유지하거나, content-dependent scores나 routing을 통해 selection problem 및 추가 overhead를 발생시킨다. 이러한 한계점은 model quality와 long-range retrieval을 유지하면서 training 및 inference cost를 줄일 수 있는 새로운 sparse attention 접근 방식의 필요성을 제기한다.
3. Method & Key Results
본 논문은 KV heads 전반에 걸쳐 causal history에 대한 접근을 분산하는 CoWindow Attention (CoWA)을 제안한다. CoWA는 모든 KV heads가 recent context를 위한 near-diagonal window와 sequence의 시작을 위한 prefix-sink window를 공유한다 [Figure 1]. 동시에, 나머지 causal distances는 complementary long-range windows로 partition되어 각 KV head에 할당된다. 이 position-defined attention pattern은 learned router나 indexer 없이 full causal coverage를 collective property로 제공하며, KV-head tensor parallelism과 정렬된다.
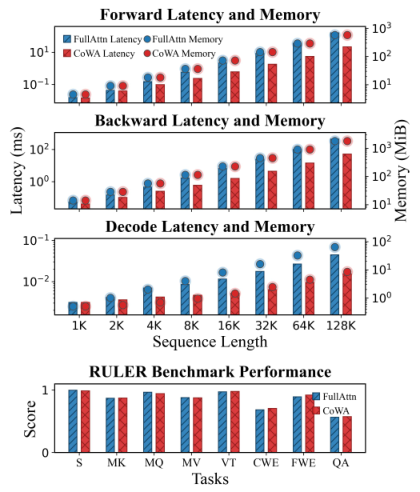
Figure 1 — CoWindow Attention 개요
주요 실험 결과에 따르면, CoWA는 associative-recall 작업에서 FullAttn과 comparable한 model quality를 달성한다. 특히, 8K tokens에서의 window-matched collective-coverage ablation 결과, CoWA는 89.73%의 accuracy를 기록하여 FullAttn의 89.97%와 거의 일치한다. 이는 complementary long-range allocation의 이점을 명확히 보여준다. Efficiency 측면에서, 128K tokens에서 8개의 H100 GPU와 tensor parallelism을 사용한 attention-operator benchmark에서 CoWA는 training 시 forward latency를 7.4배, backward latency를 8.6배 감소시켰으며, inference 시 decoding latency를 3.0배 줄였다 [Figure 3]. 또한, CoWA의 per-rank peak operator memory는 training 시 FullAttn과 동일하고 decoding 시 7.6배 낮았다. Scaling-law training 결과, 0.6B에서 14B parameters에 이르는 모델에서 CoWA는 perplexity 측면에서 FullAttn과 유사한 성능을 보였고, 14B 모델의 32K-context training에서 total training FLOPs를 28.5% 감소시켰다 [Figure 4]. Model-level evaluation에서는 14B 및 32B 모델 모두 knowledge, reasoning, long-context retrieval scores에서 FullAttn과 comparable한 결과를 나타냈다 [Table 2].
4. Conclusion & Impact
본 논문은 CoWindow Attention (CoWA)을 도입하여 full causal coverage가 각 attention head가 history를 duplicate하는 대신, head ensemble의 collective property로 달성될 수 있음을 효과적으로 입증했다. 이 structured attention architecture는 shared near 및 sink windows와 complementary long-range windows를 활용하며, position-defined window rule을 통해 training과 inference 모두에 적용된다. CoWA는 learned router나 indexer 없이 duplicated long-range access를 줄이면서 model quality와 long-range retrieval 능력을 유지한다.
이 연구는 long-context language models의 training 및 inference efficiency를 획기적으로 향상시키는 scalable sparse attention architecture를 제공한다. CoWA는 computation 및 memory traffic을 크게 줄이면서도 FullAttn에 comparable한 perplexity, knowledge, reasoning, long-context retrieval performance를 유지함으로써, Long-Context LLMs 개발에 있어 중요한 impact를 미친다. 특히 tensor parallelism과의 정렬은 대규모 분산 환경에서의 실용적인 배포 가능성을 높인다.
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] MassAlloc Attention: Let Attention Allocate Its Own Compute
- [논문리뷰] BEAVER: A Training-Free Hierarchical Prompt Compression Method via Structure-Aware Page Selection
- [논문리뷰] FlashPrefill: Instantaneous Pattern Discovery and Thresholding for Ultra-Fast Long-Context Prefilling
- [논문리뷰] HySparse: A Hybrid Sparse Attention Architecture with Oracle Token Selection and KV Cache Sharing
- [논문리뷰] QwenGyre: An Elastic Reinforcement Learning Framework for Training xLong-Horizon Agents
Review 의 다른글
- 이전글 [논문리뷰] Change the Product, Keep the Parameters: Associative Algebra Layers for Transformers
- 현재글 : [논문리뷰] CoWindow Attention: Full Causal Coverage Is a Collective Property
- 다음글 [논문리뷰] CompoWorld: Compositional Environment Scaling for General Agents
댓글