[논문리뷰] miniTE: Diagnosing and Bridging the Execution Gap in Native NVFP4 Reinforcement Learning
링크: 논문 PDF로 바로 열기
The browsing was successful. I have the content of the paper. Now I need to extract information and format it according to the instructions.
Part 1: Summary
Metadata:
- Authors: Zhen Li, Mingfa Feng, Yiming Zhang, Yang Yu, Changhai Zhou, Pengxiang Li, Dongkuan Wu, Congkai Xie, Hongxia Yang, et al.
- Keywords:
NVFP4,Reinforcement Learning,Execution Gap,LLM,Quantization,MoE,Throughput,Numerical Stability
1. Key Terms & Definitions:
- NVFP4: NVIDIA-specific 4-bit floating-point format combining E2M1 values with E4M3 block scales and an outer FP32 scale for efficient low-precision computation.
- Execution Gap: 동일한 모델 가중치 및 수치 형식에도 불구하고, 학습(learner) 엔진과 샘플링(sampler) 엔진 간에 발생하는 정책 평가(policy evaluation) 불일치.
- W4A4: 4-bit Weights and 4-bit Activations를 의미하며, expert forward GEMM 연산에 사용되는 낮은 정밀도 계산 방식을 지칭한다.
- GEMM (General Matrix Multiply): 행렬 곱셈 연산을 지칭하며, 특히 LLM의 expert computation에서 핵심적인 계산이다.
- TIS (Truncated Importance Sampling): Learner-to-sampler likelihood ratio를 사용하여 정책 기울기(policy-gradient) 기여도를 재조정하는 방법으로, learner–sampler likelihood difference를 보정하는 데 사용된다.
2. Motivation & Problem Statement: 본 논문은 Large Language Models (LLMs)의 Reinforcement Learning (RL)에서 Native NVFP4 연산을 활용할 때 발생하는 Execution Gap 문제를 진단하고 해결하고자 한다. 기존 연구들은 4-bit weight storage 및 native 4-bit training을 통해 다양한 execution path를 다루었으나, 동일한 모델 가중치와 수치 형식을 사용하더라도 training engine과 sampling engine 간에 일관된 policy evaluation을 보장하기 어려운 한계점이 있었다. NVFP4는 scale domains, rounding, accumulation, operator composition 등에서 다양한 선택지를 제공하며, 단순히 format name만으로는 이러한 세부 사항들이 명시되지 않아 cross-engine numerical execution의 불투명성을 야기한다. 특히 RL에서는 learner와 sampler가 계산하는 확률이 importance ratio와 clipping decision에 직접적으로 영향을 미치므로, 구현상의 미세한 차이가 최적화 과정에 큰 영향을 미칠 수 있다. 저자들은 이러한 실행 불일치(execution mismatch)가 NVFP4 환경에서 log-probability tail을 확대시키는 것을 확인하였으며 [Figure 1], 이는 기존의 낮은 정밀도 계산 방식이 안정적인 학습을 저해할 수 있음을 시사한다.
3. Method & Key Results: 저자들은 miniTE라는 경량 프레임워크를 제안하여 cross-engine numerical alignment를 달성하고 효율적인 native W4A4 GEMM 연산을 구현한다 [Figure 2]. miniTE는 Execution Specification을 명시하여 scale domains, rounding, logical layouts, casts 및 router coefficients의 배치 등을 기록하며, 이를 통해 cross-engine numerical behavior를 진단하고 통제한다. 제안하는 native NVFP4 학습 경로는 각 dispatched activation row가 고유한 outer scale을 가지며, 이를 통해 token-grouping 차이를 해소한다. 또한, native accumulation과 epilogue rescaling을 통해 FP4 arithmetic gains가 더 빠른 learner updates로 이어지도록 최적화하며, backward path는 saved BF16 activations 및 weights를 사용하여 high-precision gradient를 유지한다. Quantization과 Grouped GEMM의 Joint Design을 통해 packed FP4 codes, block scales, outer-scale 정보를 연속적인 buffer에 직접 저장하여 repeated splitting 및 argument preparation 오버헤드를 줄인다.
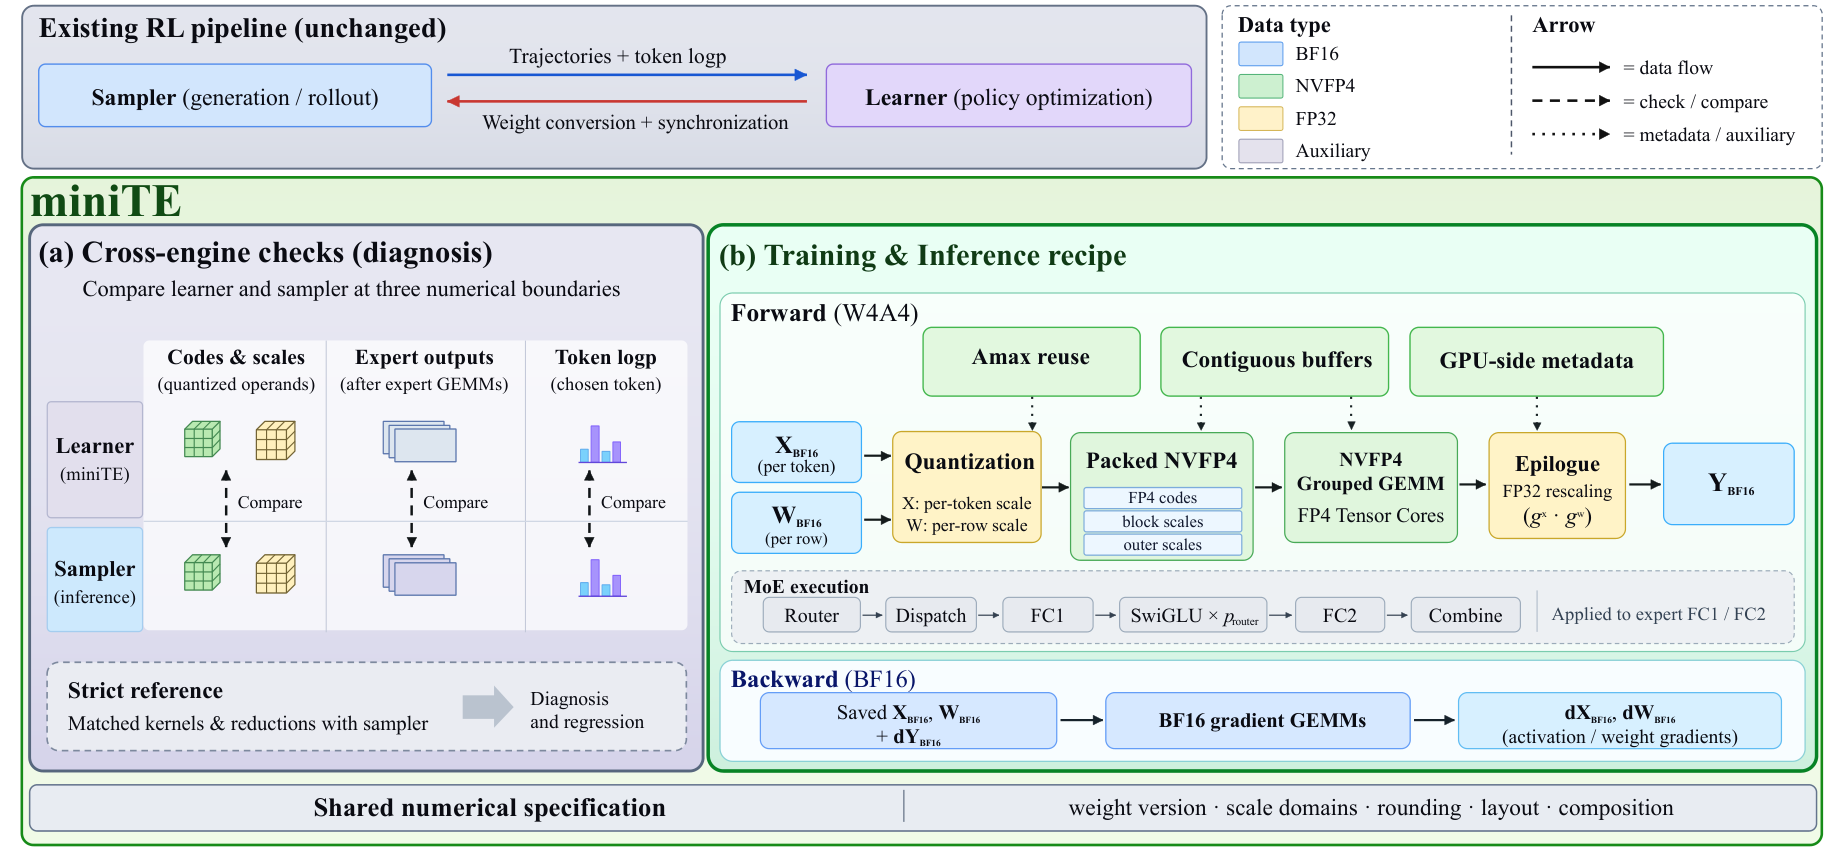
Figure 2 — miniTE 아키텍처
실험 결과, Qwen3-30B-A3B 모델에 대한 장기 RL 학습에서 miniTE는 안정적인 학습을 지속했으며, naive Transformer Engine (TE) NVFP4 대비 모든 네 가지 수학 벤치마크에서 더 높은 평가 점수를 달성했다. 특히 AIME 2024 및 AIME 2025에서 각각 10.00 및 3.88 percentage points의 성능 향상을 보였다 [Table 1]. 전체 learner updates 처리량 측면에서, 최적화된 miniTE 경로는 NVIDIA B300 GPU에서 33,540 tokens/s를 달성하여 BF16 대비 1.39배, TE NVFP4 대비 1.47배의 처리량 향상을 보였다 [Table 2]. 동일한 forward recipe 하에서 모듈별 비교 시, miniTE는 expert-forward에서 TE U3045 대비 2.46배의 속도 향상을 보여, 구현 효율성을 입증했다.
4. Conclusion & Impact: 본 논문은 frozen-policy 및 routing-conditioned 측정을 통해 기존 NVFP4 방식으로는 해결되지 않는 cross-engine execution differences를 명확히 진단했다. 저자들은 이러한 진단을 바탕으로 cross-engine diagnostics, native W4A4 forward path, independently selected BF16 backward precision, 그리고 jointly optimized quantization 및 grouped GEMM을 통합한 프레임워크인 miniTE를 성공적으로 개발했다. miniTE는 Qwen3-30B-A3B 모델에서 장기 RL 학습의 안정성을 확보하고, 수학 벤치마크에서 naive TE NVFP4를 능가하는 성능을 보였다. 특히, 최적화된 learner는 BF16 및 TE NVFP4 대비 각각 1.39배 및 1.47배의 상당한 처리량 향상을 달성하며, native low-bit computation의 실질적인 이점을 입증했다. 이 연구는 configurable numerical recipes, replaceable expert operators, 그리고 reproducible launch environments를 제공하여 native low-bit RL 분야에서 numerical 및 systems co-design을 위한 확장 가능한 기반을 마련했다는 점에서 학계 및 산업계에 큰 영향을 미칠 것으로 기대된다.
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] LLMs4All: A Review on Large Language Models for Research and Applications in Academic Disciplines
- [논문리뷰] Δτ-Bench: Pushing Agents Toward a Moving Capability
- [논문리뷰] iPrefBench: A User-Centric Benchmark for Personalized Mobile Use Agents
- [논문리뷰] WorldCast: World-Consistent Character Video Generation with Large-Angle Camera Control
- [논문리뷰] World-in-Context: Interactive Video World Modeling with In-Context Conditioning
Review 의 다른글
- 이전글 [논문리뷰] iPrefBench: A User-Centric Benchmark for Personalized Mobile Use Agents
- 현재글 : [논문리뷰] miniTE: Diagnosing and Bridging the Execution Gap in Native NVFP4 Reinforcement Learning
- 다음글 [논문리뷰] Δτ-Bench: Pushing Agents Toward a Moving Capability
댓글