[논문리뷰] AlayaVista: Streaming World Modeling from Panoramic States to Perspective Video
링크: 논문 PDF로 바로 열기
저자: Jiaming Tan, Mingliang Zhai, Zhen Li, Yuwei Wu, Chuanhao Li, Kaipeng Zhang
1. Key Terms & Definitions (핵심 용어 및 정의)
- Panoramic State:
AlayaVista내에서omnidirectional,camera-centereddynamic representation을 지칭하며,latent space에서full angular context를 유지하는 역할을 합니다. - Equirectangular Projection (ERP): 360도
panoramic이미지 및 비디오를 나타내는 표준format으로,AlayaVista의global context처리 및 데이터annotation에 사용됩니다. - Latent Viewport Renderer:
panoramic latent state를 요청된viewport에 따라low-resolution perspective video latents로mapping하는module입니다. - Perspective Video Refiner:
low-resolution perspective video latents의fine details를 복원하고visual artifacts를 억제하며super-resolution을 수행하는component입니다. - Chunk-Autoregressive Generation:
video generation을latent chunk단위로 수행하는strategy로, 각chunk내에서는bidirectional attention을,chunk간에는causal attention을 사용하여 효율적인streaming을 가능하게 합니다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
Interactive video world models은 camera motion 하에서 broad scene context를 유지하고, high-fidelity observations를 low latency로 생성해야 하는 중요한 과제에 직면해 있습니다. 기존 perspective models은 local views에만 작동하며 off-screen content를 long rollouts 동안 보존하는 데 어려움을 겪어, long-context attention이나 explicit spatial memories와 같은 복잡한 memory mechanisms을 필요로 합니다. 반면, panoramic representations은 complete angular coverage를 제공하지만, interactive user는 한 번에 하나의 perspective viewport만 관찰하므로 full-sphere에 대한 high-fidelity generation은 계산적으로 비효율적입니다. 또한, Gaussian splats나 point clouds와 같은 explicit 3D world-building methods는 geometric persistence를 제공하지만, geometric lifting 및 scene construction을 위한 추가 stages를 도입합니다. 본 연구의 핵심 문제는 video world model이 display quality로 모든 방향을 synthesize하거나 explicit 3D world representation을 먼저 구성하지 않고도 broad visual context를 유지할 수 있는지 여부이며, 이는 spatial scope와 synthesis cost 사이의 본질적인 trade-off를 해결하는 것입니다.
3. Method & Key Results (제안 방법론 및 핵심 결과)
본 논문은 panoramic world evolution과 perspective observation synthesis를 decouple하는 camera-controllable streaming video world model인 AlayaVista를 제안합니다. AlayaVista는 단일 perspective image에서 시작하여 pretrained panorama expansion model을 사용하여 360-degree scene prior를 구축한 후, camera-conditioned panoramic latent state로 scene을 evolve시킵니다. 이 panoramic state는 omnidirectional하고 camera-centered dynamic representation으로, full angular context를 유지하지만 최종 display-quality output으로 decode되지 않습니다. 대신, Latent Viewport Renderer가 이 panoramic state와 target perspective camera parameters를 low-resolution perspective video latents로 mapping하며, 이어서 Perspective Video Refiner가 fine details를 복원하고 visual artifacts를 억제하며 super-resolution을 수행합니다. AlayaVista의 architecture는 Figure 2에 제시되어 있습니다. 효율적인 streaming을 위해, panoramic generator는 chunk-autoregressive generation으로 adapt되며, panoramic generation과 perspective refinement 모두 few-step processes로 distill됩니다. 이러한 training strategy는 Figure 3에 자세히 설명되어 있습니다. 이 design을 지원하기 위해, 저자들은 large-scale real-world panoramic video dataset인 MUGEN을 구축했으며, 이는 1,318시간의 4K resolution 이상의 video와 풍부한 semantic 및 geometric annotations를 포함합니다. MUGEN 데이터셋 구축 pipeline은 Figure 4에 제시되어 있습니다.
Quantitative evaluation 결과, AlayaVista는 visual quality와 camera controllability에서 뛰어난 성능을 보였습니다. MUGEN-HQ 데이터셋 200개 evaluation cases에서, AlayaVista는 기존 baseline 모델인 MoVerse 및 HY-World 2.0 대비 더 나은 reference agreement를 달성하여 SSIM은 0.4616, LPIPS는 0.5321 (낮을수록 좋음), PSNR은 14.108을 기록했습니다. Temporal consistency 측면에서는 Consistency score 0.9240으로 가장 높은 점수를, perceptual quality에서는 Quality score 0.5579를 달성했습니다. 특히, camera control 능력에서 AlayaVista는 가장 낮은 rotation error (2.132)를 기록하여 target camera orientations를 더 정확하게 추적하는 능력을 입증했습니다. 이러한 결과는 global-state와 local-observation decomposition이 coherent camera-controlled generation에 효과적임을 보여줍니다 [cite: 1, Table 1].
4. Conclusion & Impact (결론 및 시사점)
본 논문은 global panoramic world evolution과 local perspective observation synthesis를 decouple하는 AlayaVista라는 camera-controllable streaming video world model을 성공적으로 제안했습니다. AlayaVista는 panoramic video latents를 internal dynamic state로 활용함으로써 omnidirectional scene context를 유지하면서도 expensive high-fidelity computation을 사용자에게 표시되는 viewport에만 집중시켜 computational efficiency를 높였습니다. 이러한 global-to-local architecture는 perspective-only world modeling과 explicit 3D scene construction 사이의 실용적인 중간 지점을 제시하며, complete sphere를 display quality로 synthesize할 필요 없이 broad visual context를 유지할 수 있음을 보여줍니다. 또한, 본 연구는 AlayaVista의 training을 지원하기 위해 large-scale real-world panoramic video dataset인 MUGEN을 구축하여 해당 분야의 data infrastructure를 크게 강화했습니다. 이 연구는 interactive world modeling 분야에서 perspective-video quality, camera controllability, long-horizon stability, 그리고 end-to-end streaming efficiency를 동시에 개선할 수 있는 새로운 paradigm을 제시합니다.
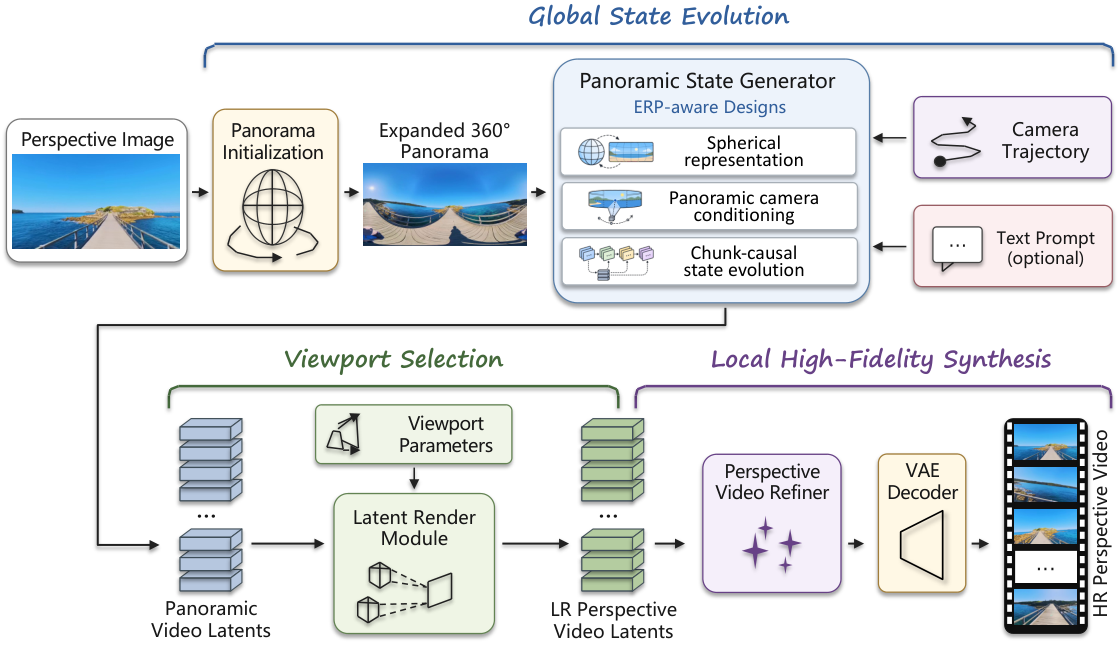
Figure 2 — 제안 모델의 전체 아키텍처
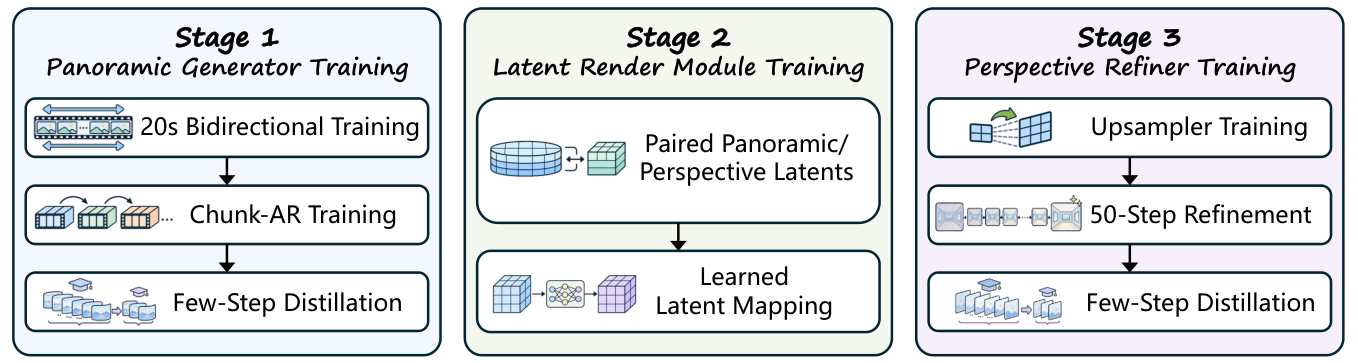
Figure 3 — AlayaVista 훈련 단계
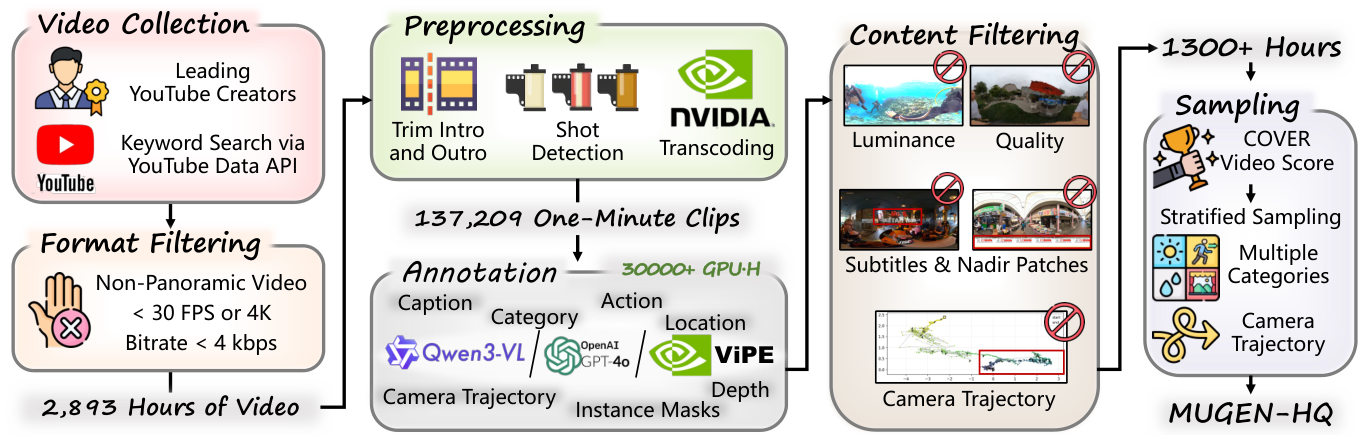
Figure 4 — MUGEN 데이터 구축 파이프라인
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] Causal Motion Diffusion Models for Autoregressive Motion Generation
- [논문리뷰] Matrix-3D: Omnidirectional Explorable 3D World Generation
- [논문리뷰] MetaView: Monocular Novel View Synthesis with Scale-Aware Implicit Geometry Priors
- [논문리뷰] Learning Transferable Dynamics Priors from Action to World Modeling
- [논문리뷰] MilliVid: Hierarchical Latents for Long-Range Consistency in Video Generation
Review 의 다른글
- 이전글 [논문리뷰] Agent as Policy for Robotic Manipulation
- 현재글 : [논문리뷰] AlayaVista: Streaming World Modeling from Panoramic States to Perspective Video
- 다음글 [논문리뷰] Atria Dawn: The Dawn of Agentic Superintelligence
댓글