[논문리뷰] EdgeWise: Bringing Long-Horizon Agents to the Edge via Selective Cloud Delegation
링크: 논문 PDF로 바로 열기
저자: Zeru Shi, Jindong Jiang, Ryo Hachiuma, et al.
1. Key Terms & Definitions (핵심 용어 및 정의)
- Long-Horizon Agents: 복잡하고 여러 단계로 이루어진 task를 수행하는 AI agent.
- SLM (Small Language Model): local device에 배포되어 primary solver 역할을 하는 비교적 작은 규모의 언어 모델.
- LLM (Large Language Model): cloud 인프라에 배포되어 더 강력한 capability를 제공하는 대규모 언어 모델.
- Selective Cloud Delegation: SLM이 task를 수행하는 동안, critical step에 한해 cloud LLM에게 처리 권한을 위임하는 전략.
- Step-level RL: SLM이 task solving과 함께 delegation 결정을 최적화하도록 학습시키는 Reinforcement Learning 방식.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
본 논문은 complex하고 long-horizon task를 수행하는 agent가 cloud LLM에 전적으로 의존할 경우 발생하는 substantial inference cost 문제를 해결하고자 한다. 기존 frontier LLM 기반 agent들은 long-horizon trajectory의 모든 step에 동일한 수준의 model capability를 할당하여 비용 효율성이 낮다. 또한, 기존 model selection 방법론들은 limited long-horizon evaluation에 초점을 맞추거나 model-pool dependency 문제를 가지고 있어 실제 long-horizon task나 model pool 변화에 유연하게 대응하기 어렵다는 한계점이 존재한다. 저자들은 not all steps may require the same level of model capability라는 observation을 통해, local SLM이 primary solver 역할을 하고 critical steps에만 cloud LLM을 선택적으로 활용하는 새로운 edge-cloud collaboration framework의 필요성을 제기한다.
3. Method & Key Results (제안 방법론 및 핵심 결과)
저자들은 local SLM이 primary solver로 작동하고 필요 시 stronger cloud LLM에 critical steps을 선택적으로 위임하는 EdgeWise framework를 제안한다 [Figure 1]. EdgeWise는 두 가지 delegation mechanism을 탐구한다: external judge-based delegation과 self-delegation. External judge-based delegation은 외부 judge (예: GPT-5.4-mini)가 trajectory history를 기반으로 key steps을 동적으로 식별하여 LLM 호출 여부를 결정한다 [Figure 4]. 이 전략은 pure cloud-model baseline의 대부분의 performance를 유지하면서 cloud-model usage를 절감한다. Self-delegation은 SLM이 task solving과 delegation을 jointly optimize하도록 step-level RL method를 도입한다. 이 RL method는 SFT (Supervised Fine-Tuning)를 통해 delegation format을 학습한 후, task correctness와 cloud usage regularization term을 포함하는 trajectory-level reward와 개별 delegation decision에 대한 fine-grained step-level credit assignment를 통해 최적화된다. 특히, Write/Edit action types이 task success와 가장 강하게 연관되어 critical steps임을 발견했으며, self-delegation은 이러한 key steps에 LLM usage를 집중시키는 효과를 보인다 [Figure 3].
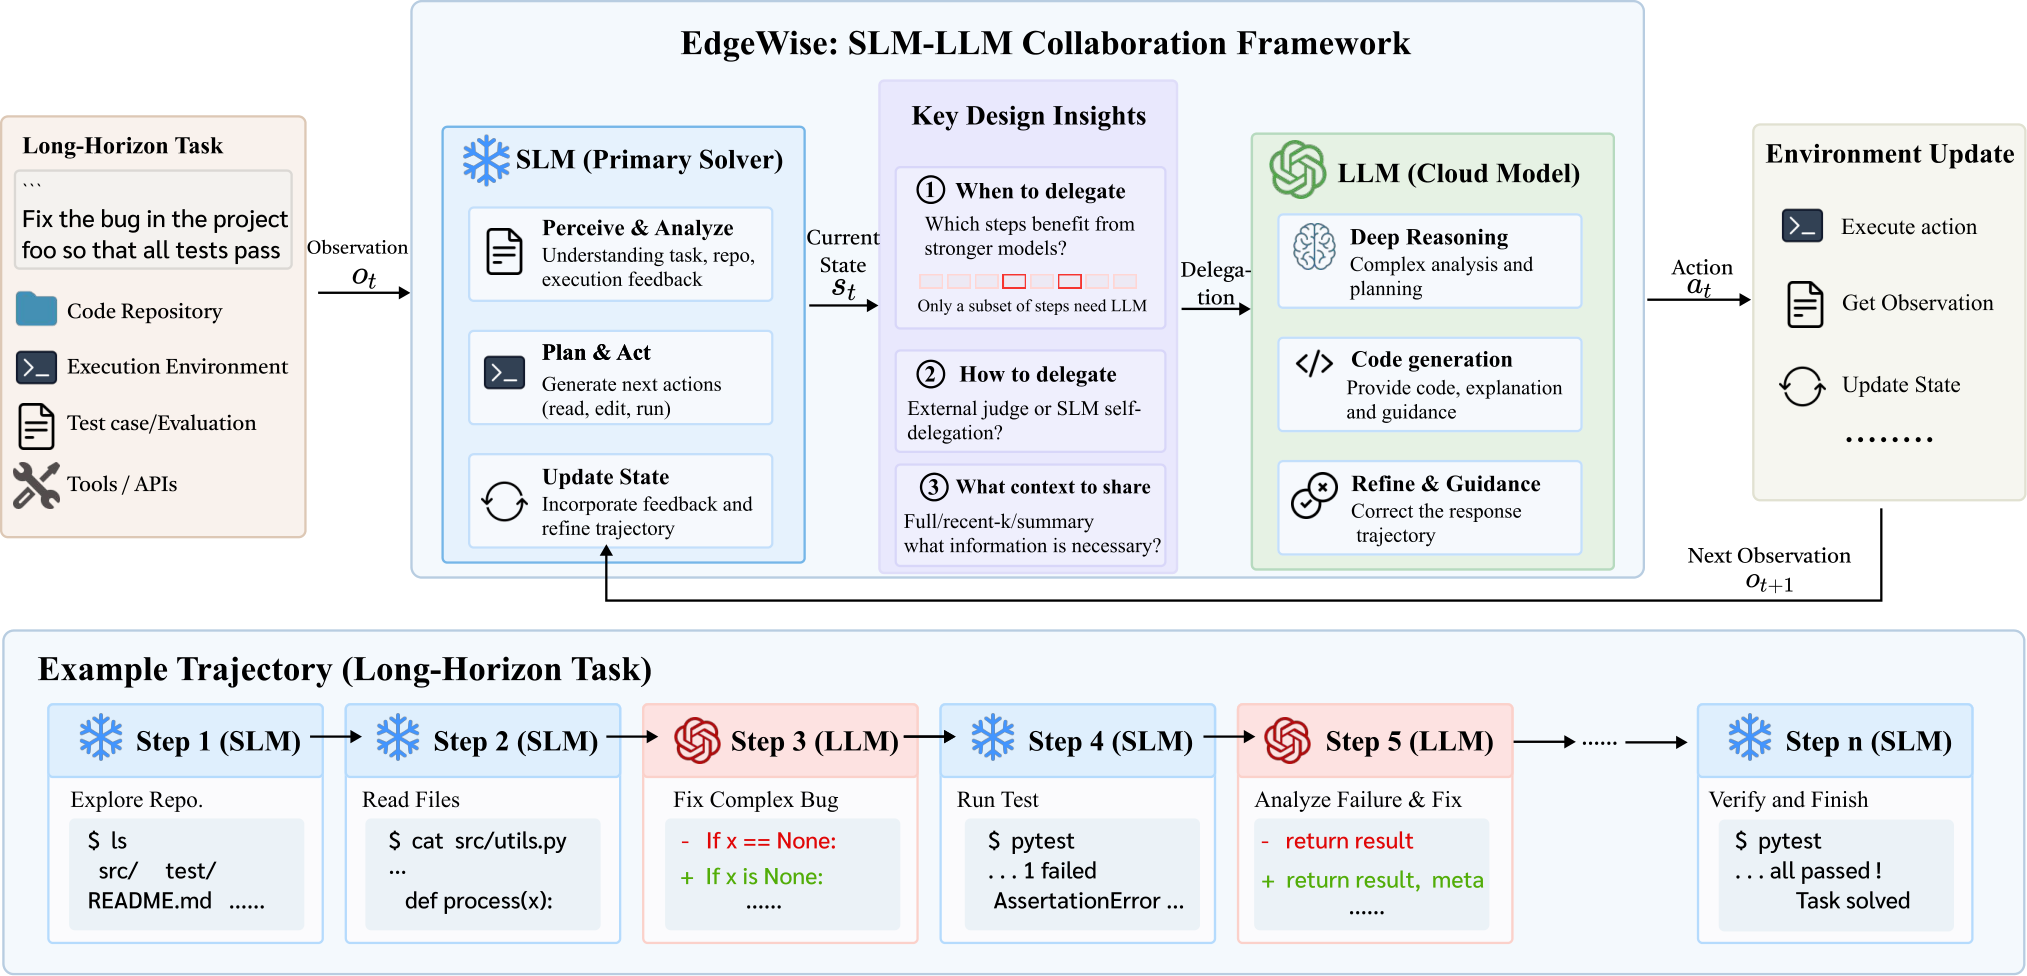
Figure 1 — 제안 모델의 전체 파이프라인
실험 결과, EdgeWise의 self-delegation 방법은 SWE-Rebench에서 Pass@3 cost를 최대 62% 그리고 Terminal-Bench 2.1에서 34%까지 감소시키면서 LLM-only performance와 동등하거나 더 나은 성능을 달성했다 [Table 1]. 예를 들어, Qwen3.5-9B와 GPT-5.5 조합에서 Terminal-Bench 2.1의 Pass@3는 82.02%로 LLM-only와 동일했지만, cost는 **279.73$**에서 **181.88$**로 감소했다. 또한, NVIDIA DGX Spark에 EdgeWise를 실제로 배포한 결과, vanilla LLM 대비 약 50%의 inference cost reduction을 달성하면서 comparable한 Pass@3 performance를 보였다 [Figure 6]. 이는 EdgeWise가 practical edge-cloud setting에서도 그 효과를 유지함을 입증한다.
4. Conclusion & Impact (결론 및 시사점)
본 연구는 local SLM과 cloud LLM 간의 효율적인 collaboration을 위한 EdgeWise framework를 성공적으로 제안한다. 핵심 observation인 "stronger intelligence는 소수의 critical steps에서 주로 필요하다"는 점을 바탕으로, EdgeWise는 이러한 steps만을 cloud model에 선택적으로 위임하고 나머지 execution은 local에서 처리한다. 이 접근 방식은 agentic coding benchmark에서 substantial cloud-model usage reduction과 competitive task performance를 동시에 달성했다. EdgeWise는 long-horizon agent systems의 효율성과 실용성을 크게 향상시킬 수 있는 step-level model collaboration의 잠재력을 입증하며, 학계 및 산업계에서 보다 cost-effective하고 scalable한 agent deployment를 가능하게 하는 중요한 시사점을 제공한다.
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] WorkRover: Scaling Long-Horizon Cowork Agent Training Via Recursive Environment Evolution
- [논문리뷰] Tev: Scaling Long-Horizon Agentic Environments with Dense Progress Rewards
- [논문리뷰] SkillGate: Training In-Policy Skill Selection in Long-Horizon Agents
- [논문리뷰] TurnOPD: Making On-Policy Distillation Turn-Aware for Efficient Long-Horizon Agent Training
- [논문리뷰] IterResearch: Rethinking Long-Horizon Agents via Markovian State Reconstruction
Review 의 다른글
- 이전글 [논문리뷰] Do Better Visual Representations Always Lead to Better End-to-End Autonomous Driving?
- 현재글 : [논문리뷰] EdgeWise: Bringing Long-Horizon Agents to the Edge via Selective Cloud Delegation
- 다음글 [논문리뷰] FDE-Gym: The Last Mile of AI Delivery
댓글