[논문리뷰] InfiniDream: Open-Ended Photorealistic 3D Worlds Through Procedural Generation
링크: 논문 PDF로 바로 열기
저자: Yi-Chuan Huang, Hao-Jen Chien, Zheng-Hui Huang, et al.
1. Key Terms & Definitions (핵심 용어 및 정의)
- Procedural Generation: 실행 가능한 프로그램(executable programs)을 통해 3D 에셋(assets)과 장면(scenes)을 생성하는 기법으로, 높은 Editability, Diversity, 그리고 Scalability를 제공한다.
- VLM (Vision-Language Model): 시각(vision) 및 언어(language) 데이터를 모두 이해하고 처리할 수 있는 모델로, 본 논문에서는 3D 콘텐츠 생성 및 편집을 지시하는 데 사용된다.
- Symbolically Constrained Asset Generation (SCE): 기존 Procedural Algorithms를 활용하여 새로운 Photorealistic Assets를 생성하면서 Editability 및 Seed-based Diversity를 보존하는 InfiniDream의 핵심 방법론이다.
- Deterministic Frustum-Guided Grid Placement: VLM 기반의 반복적인 좌표 예측 및 Costly한 렌더링 검증(render-based verification) 없이 Semantic Constraints를 정확한 3D 객체 위치(3D object positions)로 변환하는 Placement 기법이다.
- Infinigen: Photorealistic하고 Editable한 3D 장면을 생성하기 위해 Handcrafted된 Procedural Asset Factories를 포함하는 기존의 Sophisticated Procedural Generation 시스템이다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
본 논문은 Open-Ended, Photorealistic, Editable하며 Scalable한 3D World 및 Asset Generation의 핵심 문제를 해결하고자 한다. 기존의 VLM-based Code Generation은 상대적으로 Simple한 3D Assets를 생성하는 경향이 있으며, Sophisticated Photorealistic Procedural Systems는 광범위한 Manual Development를 요구한다. 또한, 기존 VLM-guided Procedural Methods는 Predefined Factories 및 API에 크게 제약되어 있어 Novel Asset Types를 생성하는 능력에 한계가 있었다. 예를 들어, VLM Harness는 Photorealistic Scenes를 덜 생성하고, Infinigen은 Predefined Factories에 국한되며, Code2Worlds는 Function Calls 및 Parameter Adjustment에만 의존한다는 제약이 있다. Mesh-based Assets 역시 Parameterized Editability 및 Seed-based Diversity가 부족하여 직접적인 Mesh Manipulation 또는 Regeneration이 필요하다는 문제점을 안고 있다.
3. Method & Key Results (제안 방법론 및 핵심 결과)
저자들은 Open-Ended Procedural 3D World Generation을 위한 VLM-driven Framework인 InfiniDream을 제안한다. InfiniDream은 크게 두 가지 핵심 구성요소로 이루어진다. 첫째, Symbolically Constrained Asset Generation (SCE)은 기존 Procedural Algorithms를 재활용하고 VLM Reasoning을 통해 새로운 Photorealistic Assets를 Predefined Factories의 범주를 넘어 생성하며, Editability와 Seed-based Diversity를 보존한다 [Figure 4, cite: 1]. 이 과정은 Factory Mapping and Retrieval, Structured Planning and Coarse Construction, 그리고 Render-guided Fine Refinement의 단계를 포함한다. 둘째, Semantic Scene Planning과 Deterministic Frustum-Guided Grid Placement를 결합한 End-to-End Text-to-World Pipeline을 통해 Large-Scale 3D Worlds를 Precise Object Placement, Procedural Population 및 Animation과 함께 구성한다 [Figure 5, cite: 1]. Deterministic Frustum-Guided Grid Placement는 Director의 Semantic Constraints를 Camera Frustum 기반의 3D Candidate Positions로 변환하며, Visibility, Collision, Inter-instance Spacing, Surface Policy, Projected-area Band 등의 Deterministic Checks를 통해 Nearest Valid Candidate를 선택한다.
InfiniDream은 100개의 Object-level Task와 20개의 Scene-level Task에 대한 광범위한 평가에서 강력한 성능을 입증했다. Object-level에서 InfiniDream은 CLIP (30.07), SigLIP2 (0.148), DINOv3 (0.554), ImageReward (-0.62)의 모든 Perceptual Metrics에서 기존 Baseline들을 능가하는 최고 점수를 기록했다. Scene-level에서도 InfiniDream은 CLIP (29.64), SigLIP2 (0.143), DINOv3 (0.361), ImageReward (-0.877)에서 Baseline Method들을 상회하는 성능을 보였다 [Figure 7, cite: 1]. 다양성 분석(Diversity Analysis) 결과, InfiniDream은 TRELLIS.2 대비 더 높은 Visual Diversity (DINOv2 Dist. 0.6704)를 달성하면서 유사한 Semantic Alignment (SigLIP2 0.1225)를 유지했다. Human Preference Study에서는 Object Level에서 Semantic Alignment 81.3%, Visual Quality 73.7%의 선호도를, Scene Level에서는 Semantic Alignment 91.0%, Visual Quality 75.3%의 선호도를 얻어 사용자로부터 높은 평가를 받았다.
4. Conclusion & Impact (결론 및 시사점)
본 논문은 InfiniDream이라는 VLM-driven Framework를 통해 Open-Ended Procedural 3D World Generation의 새로운 지평을 열었다. Symbolically Constrained Asset Generation과 Semantic Planning 및 Deterministic Placement를 결합함으로써, InfiniDream은 Novel, Photorealistic, 그리고 Editable한 Procedural Assets를 생성하고 이를 Diverse한 Large-Scale 3D Worlds로 구성하는 데 성공했다. 이 연구는 기존 Predefined Factories의 제약을 넘어선 Asset Creation과 Robust하고 Scalable한 Scene Construction을 가능하게 하여, Synthetic Data Generation 및 Game Development와 같은 분야에서 더욱 유연하고 사실적인 가상 환경을 구축하는 데 중요한 시사점을 제공한다. 향후 연구에서는 VLM-generated Animation Code를 통한 더욱 복잡한 모션 지원 및 Indoor Environments로의 확장 가능성이 제시된다.
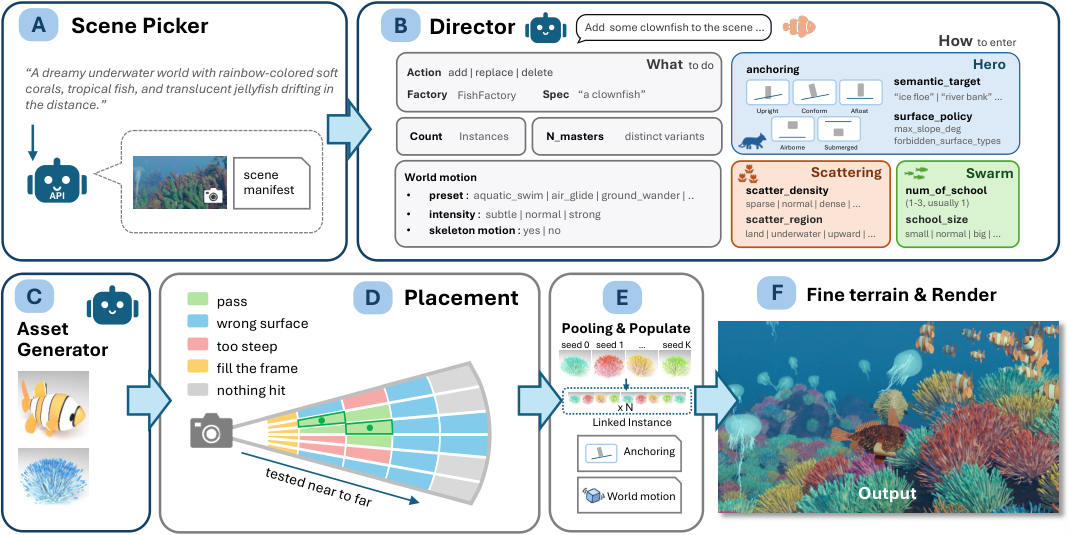
Figure 5 — InfiniDream 엔드투엔드 파이프라인
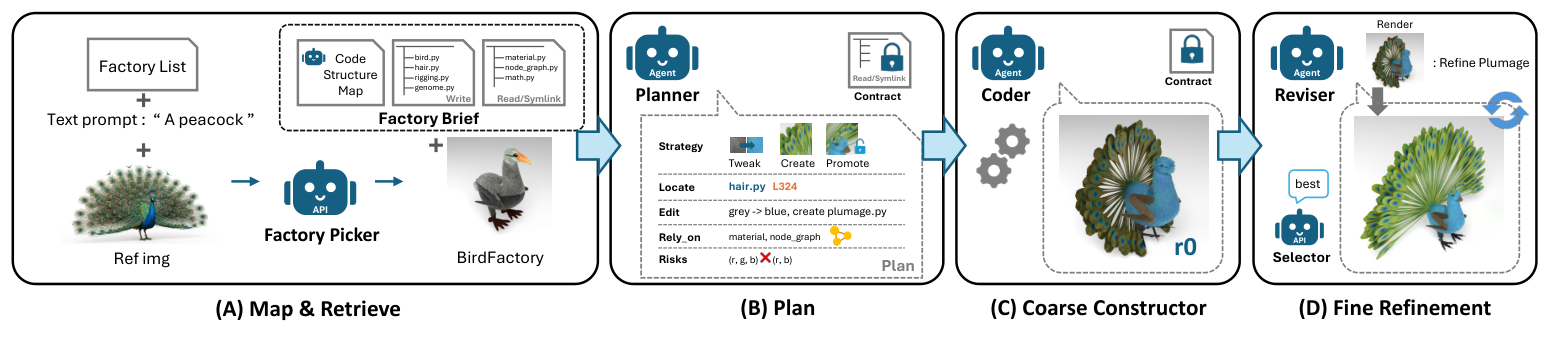
Figure 4 — SCE 자산 생성 파이프라인
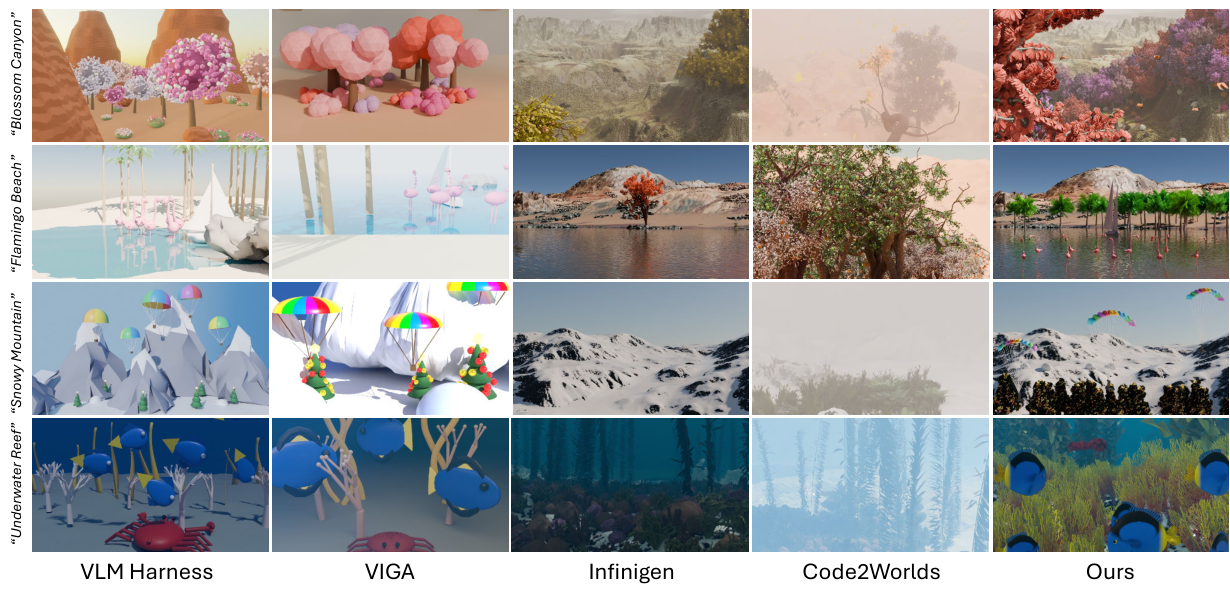
Figure 7 — 장면 생성 정성적 비교
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] WorldGen: From Text to Traversable and Interactive 3D Worlds
- [논문리뷰] Game2Real-Bench: Do Toy Games Reveal and Transfer to Real-World Visual Reasoning?
- [논문리뷰] Recursive Code World Models: Building Complex Worlds through Recursive Scene Programs
- [논문리뷰] NOLLI: A Difficulty-Calibrated Puzzle Benchmark for Diagnosing the English-Korean Performance Gap
- [논문리뷰] Trace: A Taxonomy-Guided Environment for Multidomain Visual Reasoning
Review 의 다른글
- 이전글 [논문리뷰] Holi-World: Building Holistic World Intelligence from Human-Ego Experience
- 현재글 : [논문리뷰] InfiniDream: Open-Ended Photorealistic 3D Worlds Through Procedural Generation
- 다음글 [논문리뷰] Interlock: From Local Correctness to Task Completion in Long-Horizon Agents
댓글