[논문리뷰] World Action Agent: Harnessing VLMs for Robot Manipulation via World Action Rehearsal
링크: 논문 PDF로 바로 열기
The paper "World Action Agent: Harnessing VLMs for Robot Manipulation via World Action Rehearsal" by Yehang Zhang et al. introduces a new multi-agent harness for robot manipulation. I need to summarize it according to the specified format, paying close attention to technical terms, phrasing, metadata, section structure, direct answer rule, and figure citations. I will also extract key figure information in JSON format.
Metadata Extraction:
- Authors: Yehang Zhang, Haojian Huang, Yifan Chang, Jianchong Su, Bohan Zhou, Yingjie Xu, Wosong Chen, Tianhao Zhou, Chenxu Wang, Tianyi Zhang, Yangkai Wei, Wenqian Li, Shiyuan Deng, Yinchuan Li, Ying-Cong Chen, Zexi Li.
- Keywords: VLM, Robot Manipulation, World Action Rehearsal, Embodied AI, Multi-agent Systems, Skill Learning, Reinforcement Learning, LIBERO-Pro.
Figure Extraction (Preliminary): Looking at the figures in the paper:
- Figure 1: WAA Teaser - Overall concept. Seems important.
2609.29964v1/waa_teaser.png - Figure 2: Overview of the World Action Agent (WAA) harness. This is the core architecture. Very important.
2609.29964v1/waa_method.png - Figure 3: Action rehearsal and in-view correction. Illustrates key methodologies. Important.
2609.29964v1/waa_rgbd_actions.png - Figure 4: Qualitative examples of WAA. Shows results.
2609.29964v1/waa_qualitative_cases.png - Figure 5: Success rates of Qwen3.5-9B. Important quantitative result.
2609.29964v1/waa_sft_liberopro_vs_qwen.png(Note: The figure 5 link in the text isTable 5, which is incorrect, but the image is clearly Figure 5).
I will select Figure 1, Figure 2, and Figure 3 as the most important.
Content for Part 1 - Summary:
1. Key Terms & Definitions:
- World Action Agent (WAA): VLM이 기본 도구를 사용하여 로봇을 조종하고, 모든 결정을 시각적 Action Workspace 내에서 내리도록 하는 multi-agent harness이다.
- Visual Action Workspace: WAA가 Interaction-centered Canvas, Action Rehearsal, In-view Correction의 세 가지 속성을 통해 VLM이 직접 로봇을 제어하도록 하는 인터페이스이다.
- Contact Views: 현재 로봇과 객체 간의 상호작용 주변 장면을 자동으로 선택하여 VLM에게 근접한 시야를 제공하는 View이다.
- Action Rehearsal: 각 Action을 Agent가 Imagination Agent를 통해 미리 보고 계획 피드백에 따라 수정할 수 있는 편집 가능한 Proposal로 변환하는 기능이다.
- In-view Correction: Observation, Rehearsal, Low-level Execution 사이의 Closed Loop를 형성하여 Agent가 관찰된 View에서 잔여 Offset을 직접 제거할 수 있게 하는 기능이다.
2. Motivation & Problem Statement: 기존 Vision-Language Models (VLMs) 기반 로봇 Manipulation 시스템들은 VLM을 간접적으로 활용하거나, 장면만 보여줄 뿐 VLM이 직접 Act할 수 있는 World를 제공하지 못하는 한계점을 가진다. VLA(Vision-Language-Action) 모델들은 새로운 객체, 레이아웃, Task에 대한 Generalization 능력을 학습하는 것을 목표로 하지만, VLM을 Action Prediction에 Fine-tuning하는 것이 VLM의 General Understanding 및 Reasoning 능력을 약화시킬 수 있다. World Action Models (WAMs)는 환경 Dynamics와 Action Learning을 연결하지만, 학습된 Visual Dynamics를 실행 가능한 Control에 Grounding하려면 여전히 로봇 데이터와 Action Alignment가 필요하다. 이러한 문제들로 인해 VLM이 Manipulation Decision에 직접 관여하면서도 그 General Functionality를 유지할 수 있는 새로운 접근 방식이 요구된다. 구체적으로, 기존 인터페이스들은 상호작용에 집중된 View가 부족하고, Action을 실행 전에 미리 시도해볼 수 없으며, Perception과 Action이 다른 공간에 존재하여 Offset 수정이 어렵다는 세 가지 주요 문제점을 안고 있다. 본 연구는 이러한 한계를 극복하고 범용 VLM이 로봇 Pilot 역할을 수행할 수 있도록 하는 방법에 대한 질문에 답하고자 한다.
3. Method & Key Results: 본 논문은 범용 Vision-Language Models(VLMs)이 로봇 Manipulation을 직접 조종할 수 있도록 하는 multi-agent World Action Agent (WAA) harness를 제안한다. WAA의 핵심은 VLM이 로봇을 조종할 수 있는 Visual Action Workspace를 제공하는 것이다. 이 Workspace는 세 가지 주요 속성을 갖는다: 첫째, Contact Views는 현재 상호작용 주변의 장면을 자동으로 선택하여 VLM이 Local Relation을 더 잘 이해하도록 돕는다. 둘째, Action Rehearsal을 통해 Agent는 각 Action을 실행 전에 편집 가능한 Proposal로 미리 보고 Imagination Agent의 계획 피드백을 활용하여 수정할 수 있다. 셋째, In-view Correction은 Observation, Rehearsal, Low-level Execution 간의 Closed Loop를 형성하여 Agent가 시각적 View 내에서 잔여 Offset을 직접 수정할 수 있게 한다. 이 세 가지 기능은 Calibration된 동일한 Canvas를 공유하여 Agent가 관찰, 리허설, 수정을 동일한 공간 목표에 대해 수행하도록 한다.
WAA는 또한 Embodied Procedural Knowledge를 두 가지 방식으로 습득한다. Multimodal Skill Library는 Expert Videos와 Human Teaching으로부터 Evolve되며, Skill Agent를 통해 Consulting된다. 또한, harness 내에서 기록된 Interaction Traces는 더 작은 VLM을 훈련하여 동일한 harness를 Pilot할 수 있게 한다.
실험 결과, WAA는 LIBERO-Pro 벤치마크에서 기존 State-of-the-Art를 능가하는 우수한 성능을 달성했다. LIBERO-90 데이터셋으로만 Evolved된 Skill을 사용한 WAA는 평균 75.6%의 성공률을 기록하며, ASPIRE (72.0%) 및 다른 End-to-End VLAs, Code-as-Policy Agents를 앞섰다. 특히, 센티미터 스케일의 정밀한 배치 Relation이 중요한 Spatial Split에서 WAA는 80.0% 및 73.3%의 성공률을 달성하여 기존 Baseline 대비 큰 폭의 개선을 보였다. 또한, 동일한 Skills가 추가 학습 없이 robosuite 환경에도 효과적으로 Transfer되어 Cube lift, Cube stack 작업에서 100%의 성공률을, Cube restack에서 100%의 성공률을 보였다. Harness Traces로 Qwen3.5-9B를 Fine-tuning한 결과, Out-of-Domain 성공률이 1.7%에서 43.3%로 크게 향상되어, 작은 VLM도 이 harness를 효과적으로 Pilot할 수 있음을 입증했다.
4. Conclusion & Impact: 본 연구는 범용 VLM이 Robot Manipulation Task에서 직접 의사 결정을 내리고 수정할 수 있도록 하는 World Action Agent (WAA)를 제안한다. WAA는 VLM을 재훈련하는 대신, Visual Action Workspace를 통해 상호작용 중심의 관찰, 실행 전 Action Rehearsal 및 수정, 그리고 Observation-Rehearsal-Execution 간의 Closed Loop를 제공함으로써 VLM의 Spatial Understanding을 활용한다. 이를 통해 VLM이 로봇의 Pilot으로서 기능하게 한다.
WAA는 LIBERO-Pro 벤치마크에서 75.6%의 평균 성공률을 달성하며 State-of-the-Art 성능을 입증했으며, LIBERO-90에서 Evolved된 Skills는 robosuite 환경으로 성공적으로 Transfer되었다. 또한, harness Interaction Traces를 통해 9B VLM을 Pilot으로 훈련하여 Out-of-Domain 성공률을 크게 향상시킬 수 있음을 보여주었다. 이 연구는 VLM의 범용적인 지식과 추론 능력을 유지하면서도 정밀한 로봇 제어 문제를 해결하는 새로운 방향을 제시하며, 향후 더 강력한 Multi-view Understanding을 가진 VLM backbone이 등장할 경우 WAA의 성능이 더욱 향상될 수 있는 잠재력을 가진다.
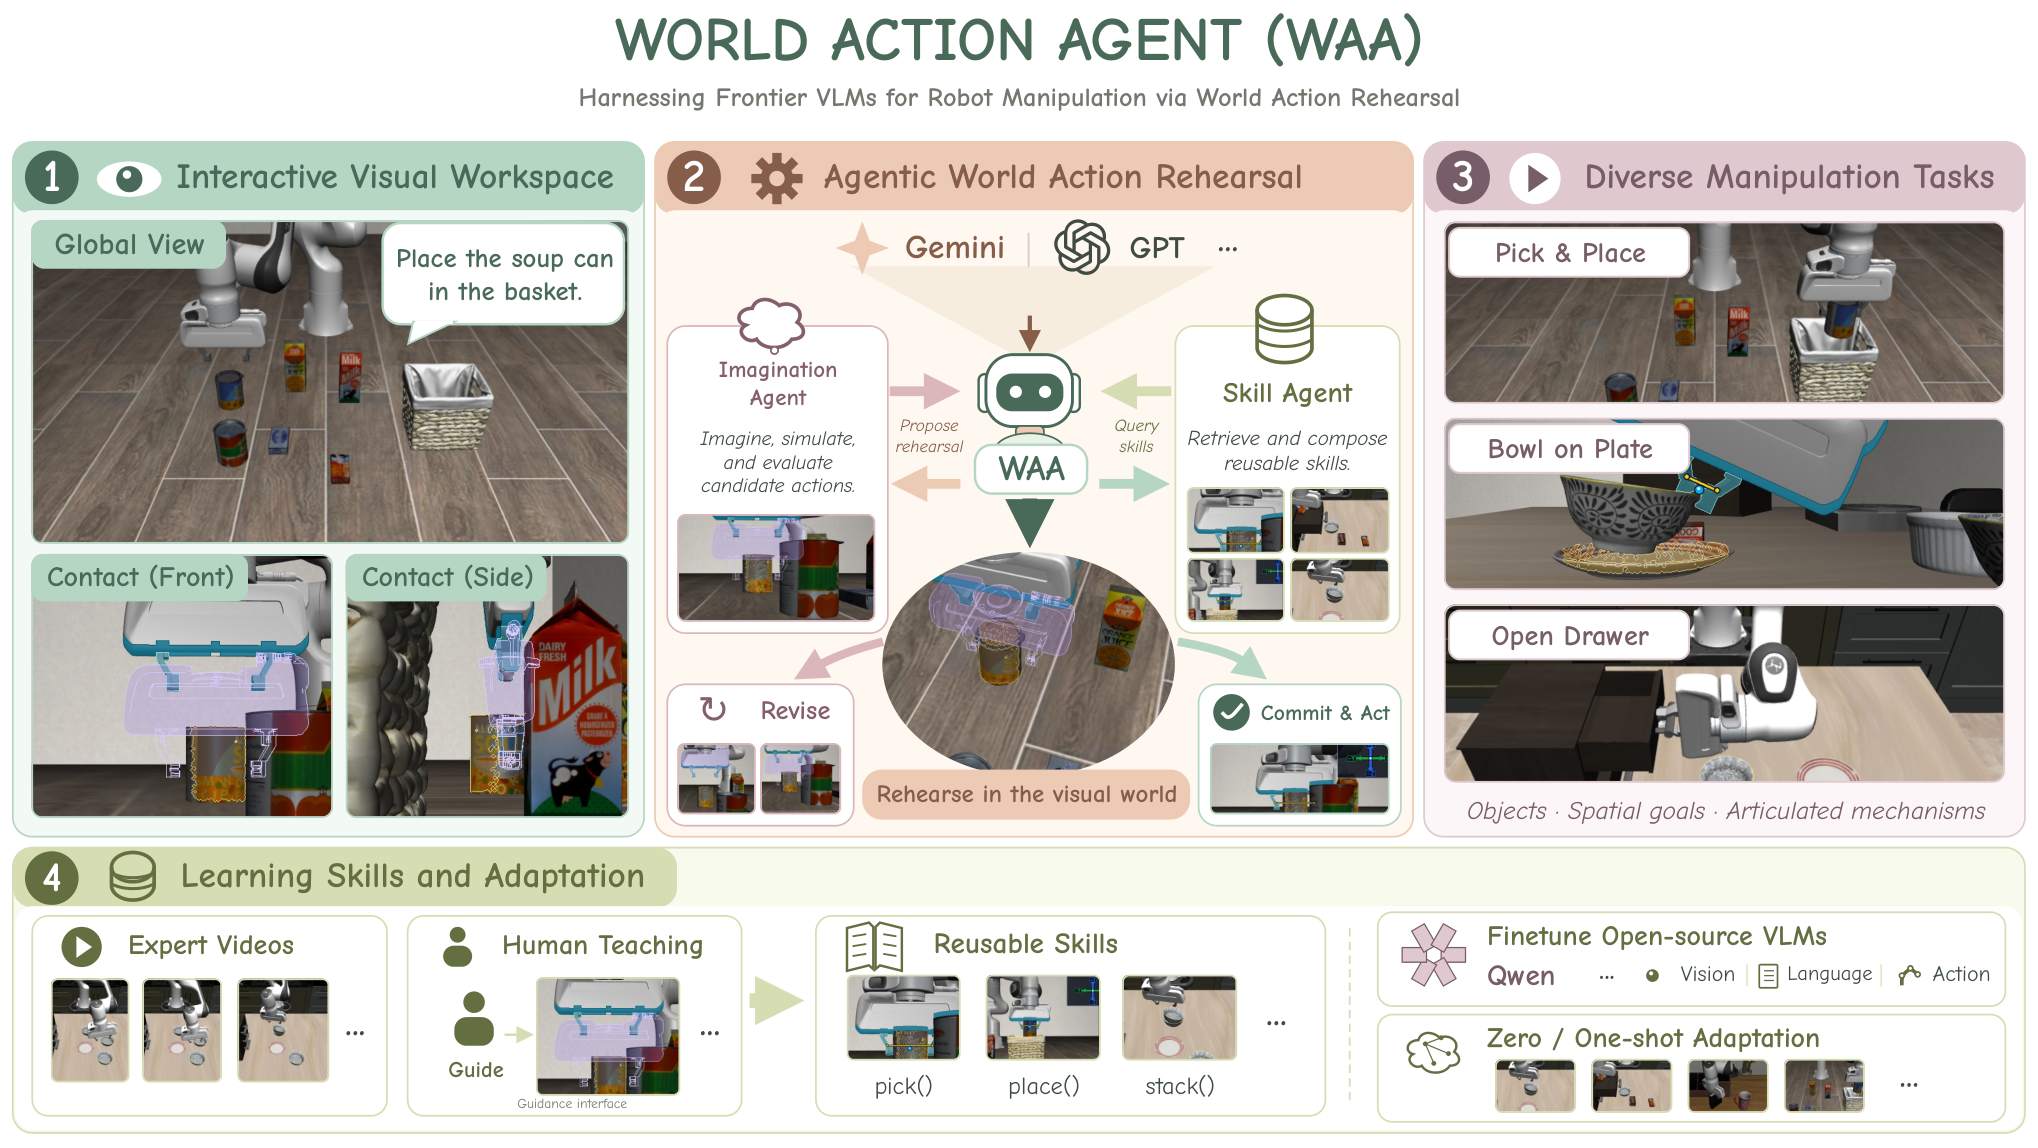
Figure 1 — WAA의 전체 개념도
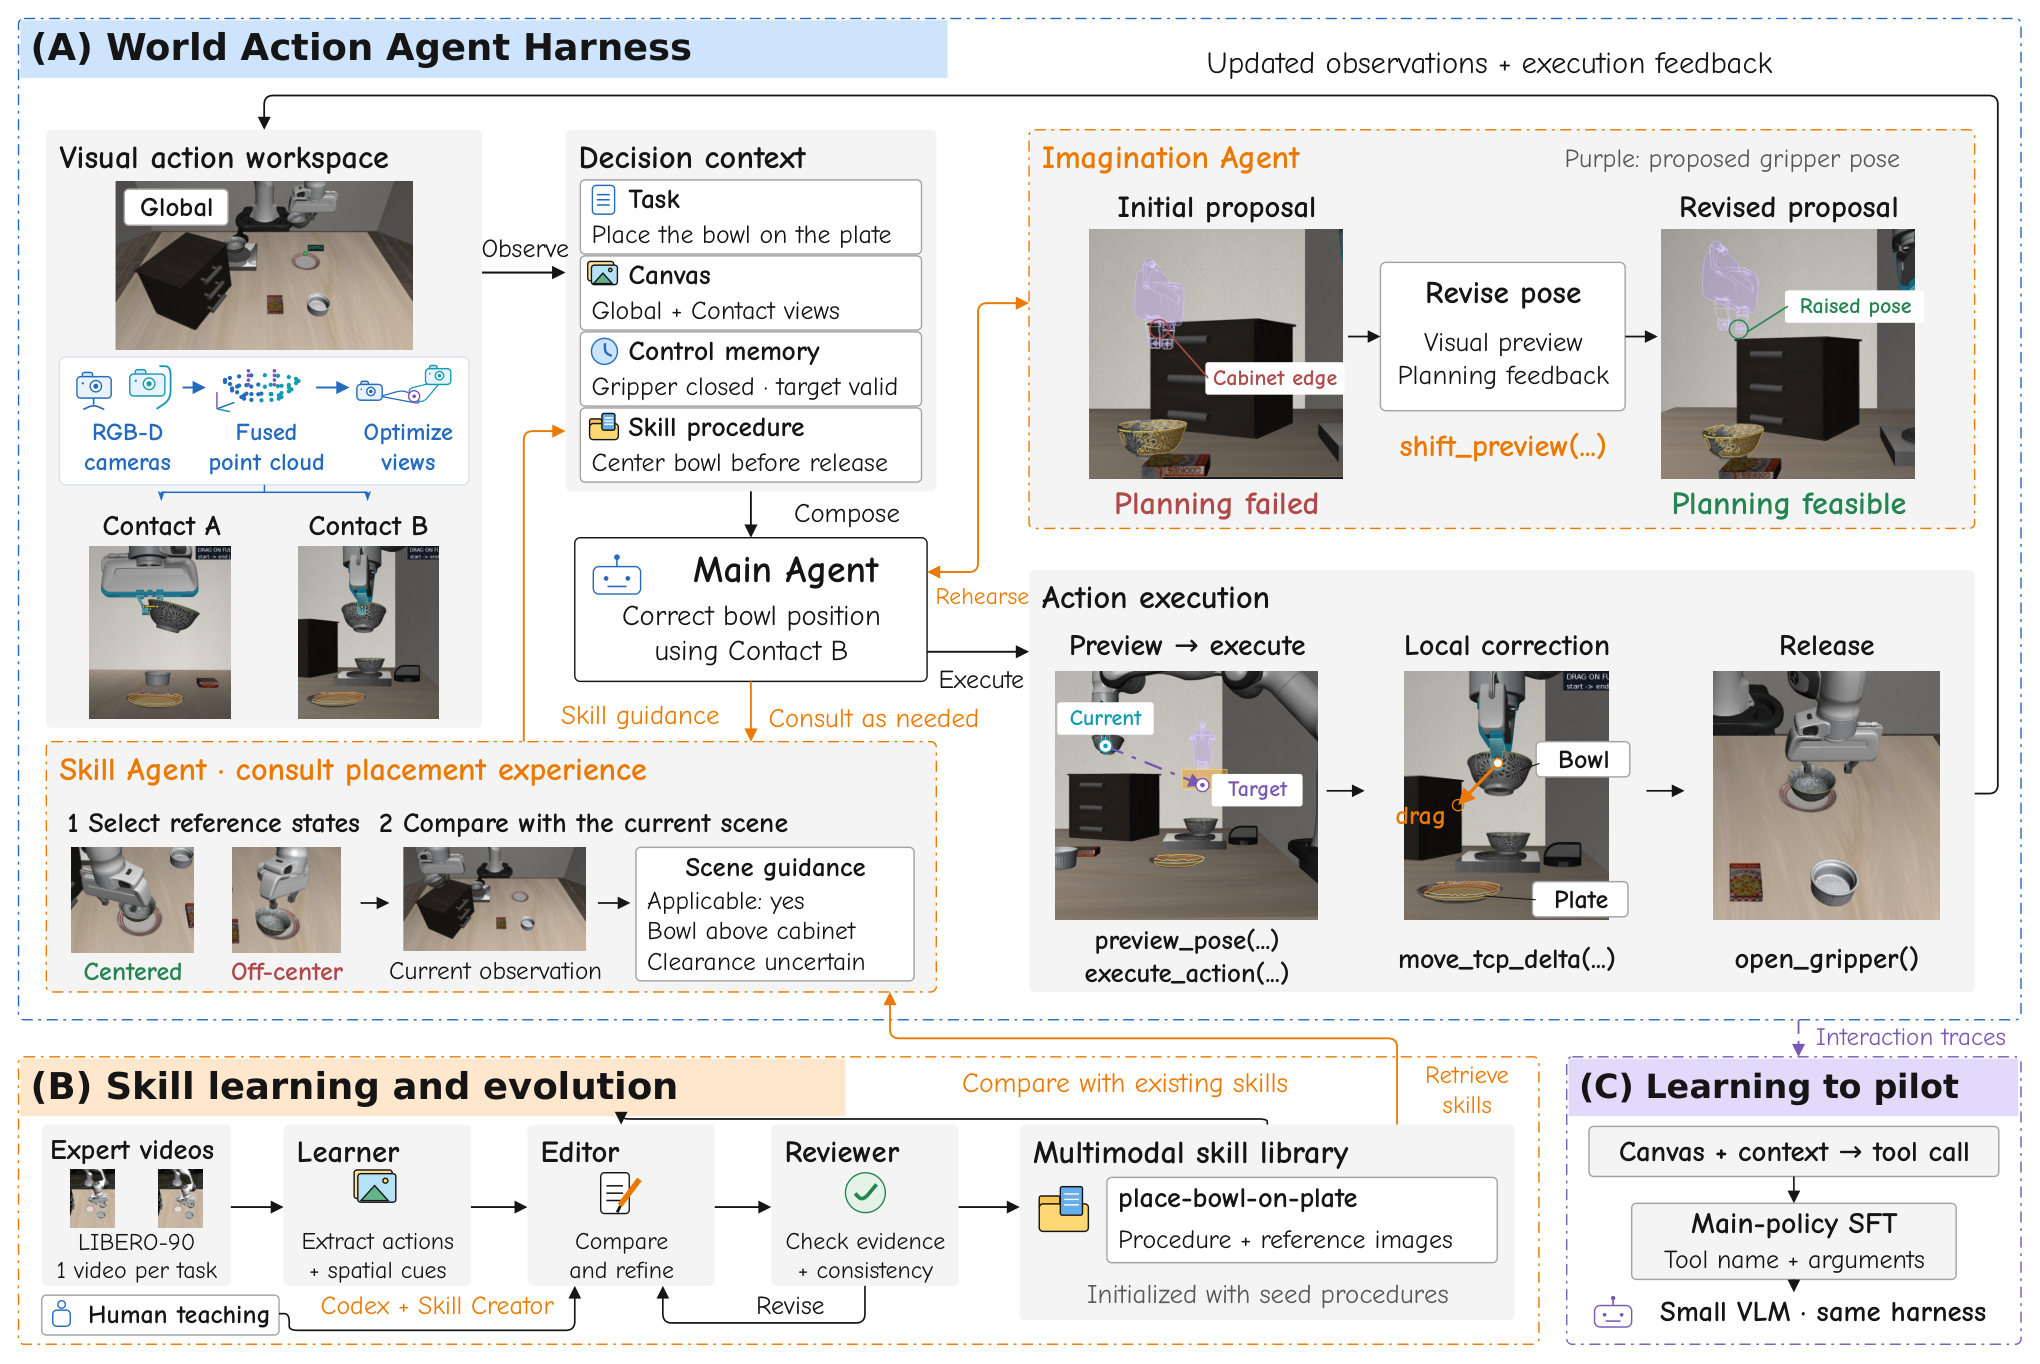
Figure 2 — WAA Harness 개요
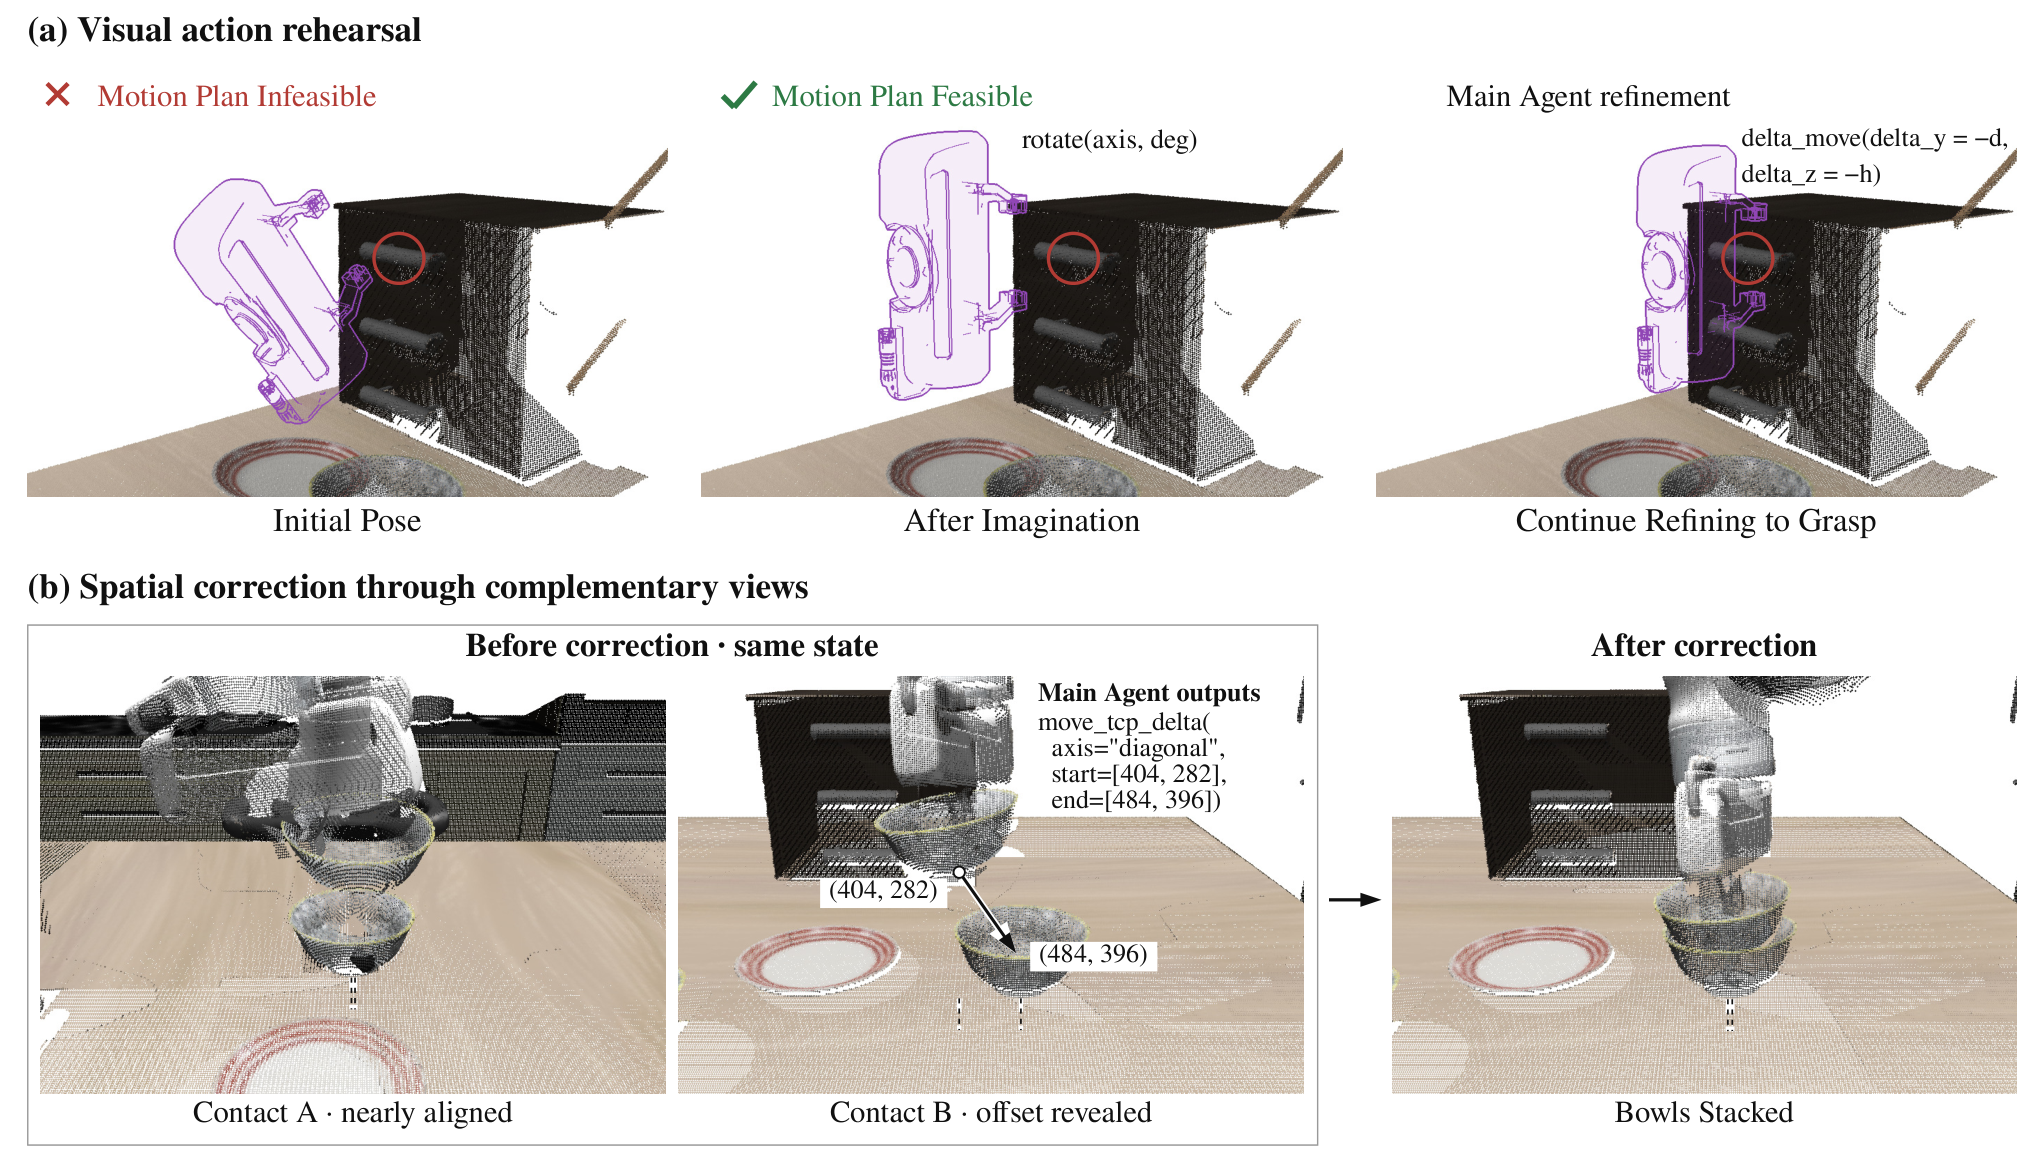
Figure 3 — Action Rehearsal 및 Correction
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] LLMs4All: A Review on Large Language Models for Research and Applications in Academic Disciplines
- [논문리뷰] ZooWork-ShopRanker: An Open, Preference-Aligned E-Commerce Reranker
- [논문리뷰] VLA-Precision: Asymmetric Co-Bootstrapping for Efficient Real-World Online RL of Vision-Language-Action Models
- [논문리뷰] TrackEverything: Long Horizon Dense Tracking via De-Duplicating 3D Scene Representations
- [논문리뷰] Tactile-JEPA: Topology-Aware Self-Supervised Representation Learning for Distributed Tactile Sensors
Review 의 다른글
- 이전글 [논문리뷰] WanPE: Towards Cinematic Prompt Enhancement for Modern Text-to-Video Generation
- 현재글 : [논문리뷰] World Action Agent: Harnessing VLMs for Robot Manipulation via World Action Rehearsal
- 다음글 [논문리뷰] Your Transformer Can Hold Two Thoughts at Once: Evidence of Linear Superposition in LLMs
댓글