[논문리뷰] InternW0-Δ: A World Action Model Bridging Predictive Dynamics and Actions with 20K+ Hours of Open Data
링크: 논문 PDF로 바로 열기

Figure 1 — InternW0-Δ의 아키텍처 개요

Figure 3 — World-Action MoT 레이어 및 어텐션 마스크

Figure 10 — 실제 로봇 태스크 실행 예시 저자: Xingyu Miao, Zizun Li, Baole Fang, et al.
1. Key Terms & Definitions (핵심 용어 및 정의)
- World Action Models (WAMs): 시각적 Dynamics와 Action 생성을 Jointly Modeling하여 범용적인 로봇 조작을 가능하게 하는 패러다임입니다.
- Causal Imprint: Inference 시점에 사용 가능한 Observation으로부터 미래와 관련된 Scene 변화를 학습하여 Action 생성에 직접 활용할 수 있도록 하는 메커니즘입니다. Future Observation은 Training Supervision으로만 사용됩니다.
- Mixture-of-Transformers (MoT): Video Expert와 Action Expert가 Scene-grounded Semantic Guidance 하에 상호작용하며 Multimodal Context Encoding을 수행하는 프레임워크입니다.
- 4D-aware Representation Distillation: Frozen Track4World Teacher 모델로부터 Geometric 및 Motion Prior를 Video Expert에 주입하여 Representation을 강화하는 Training-only Objective입니다.
- Sparse Memory Context (SMC): Episode-level Context와 Recent Interaction History를 경량화된 방식으로 유지하여 Action Prediction에 필요한 Temporal Context를 제공하는 기법입니다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
범용적인 로봇 조작을 위한 World Action Models (WAMs)는 시각적 Dynamics와 로봇 Actions을 Jointly Modeling하는 유망한 접근 방식을 제공합니다. 대규모 Video Pretraining은 Scene이 시간에 따라 어떻게 Evolution하는지에 대한 강력한 시각적 및 Temporal Knowledge를 제공하지만, 미래 Observation을 예측하는 능력은 효과적인 로봇 제어로 직접 전환되지 않는다는 핵심적인 문제가 존재합니다. Action 생성은 Task-relevant한 변화를 식별하고, Object의 Geometry 및 Motion을 이해하며, 이러한 Cues를 현재 Instruction 및 Scene에 Grounding해야 합니다. 기존 연구들의 한계점은 주로 이러한 예측적 지식을 Inference 시점에 Explicit한 미래 생성 없이 Action 생성에 직접 유용한 Representation으로 전환하는 데 어려움을 겪는다는 것입니다. 본 논문은 이러한 Challenge를 해결하기 위해 예측적 시각 Dynamics, Temporal Context, 그리고 Task-conditioned Scene Semantics를 Action 생성에 통합하는 Directed World-Action Architecture인 InternW0-Δ를 제안합니다.
3. Method & Key Results (제안 방법론 및 핵심 결과)
본 논문은 예측적 시각 Dynamics, Task-conditioned Scene Semantics, 그리고 Action 생성을 Directed World-Action Architecture 내에서 통합하는 InternW0-Δ를 제안합니다. 제안하는 모델은 Pretrained Video Expert와 Action Expert를 Directed Mixture-of-Transformers (MoT)를 통해 결합하며, Frozen Vision-Language Model (VLM)이 Scene-grounded Task Semantics를 Action Expert에 제공합니다 [Figure 1]. 또한, Causal Imprint는 Training-only Future Supervision을 통해 미래 관련 Scene 변화를 학습하여 Action Expert에 직접 예측적 Representation을 제공하며, Inference 시에는 미래 Video Rollout이 필요 없습니다. 훈련 시에만 적용되는 4D-aware Distillation은 Track4World Teacher 모델로부터 Geometric 및 Motion Prior를 Video Expert에 주입하여 Representation을 강화합니다 [Figure 2]. 이러한 Directed Information Flow는 Action Prediction 경로가 실현된 미래 Observation을 입력으로 받지 않도록 보장하여, InternW0-Δ가 미래 Video Sampling 없이 Inference 시에 직접 Actions을 예측할 수 있게 합니다.
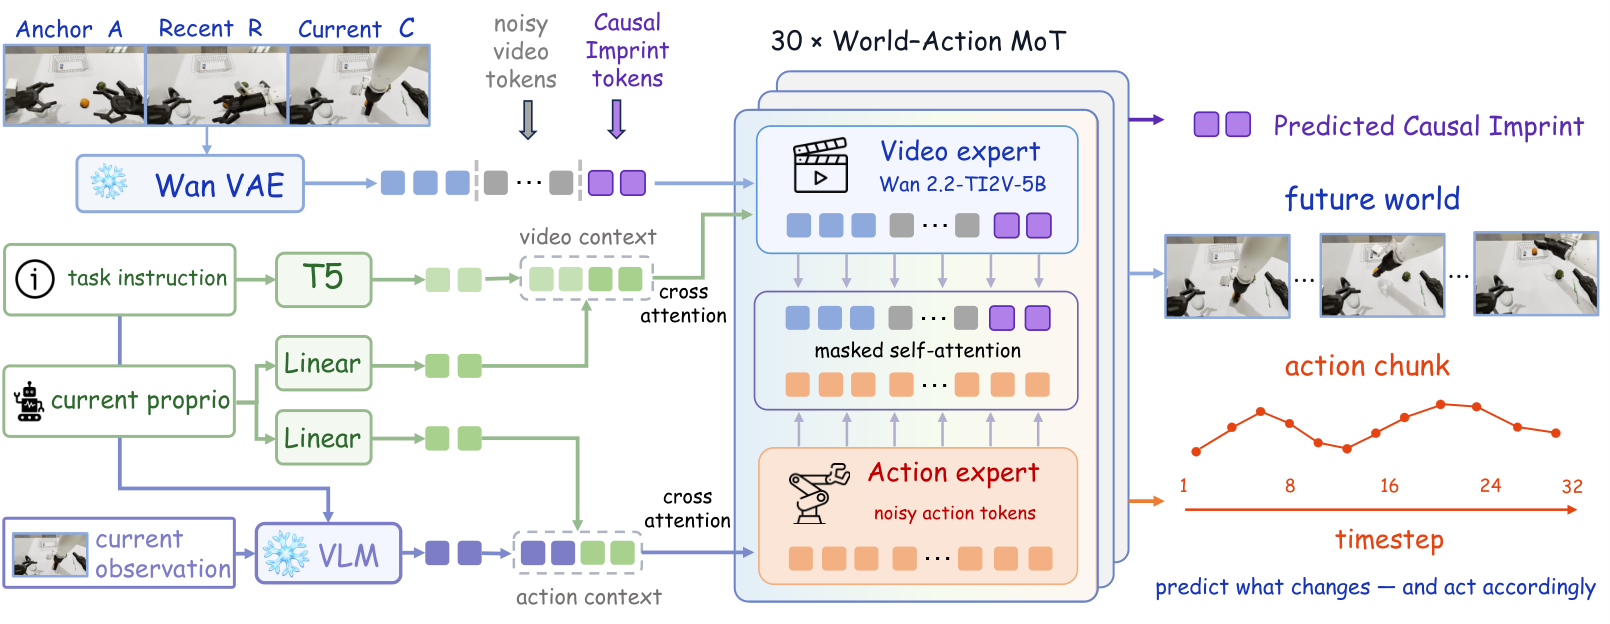
Figure 1 — InternW0-Δ의 아키텍처 개요
대규모 Joint Training을 위해, 저자들은 Robot Demonstrations, UMI Data, Egocentric Human Demonstrations, 그리고 Ego2Robot Data를 포함하는 20,000시간 이상의 대규모 Heterogeneous Corpus를 구축했습니다. 이 Corpus는 Canonical State-Action Representation으로 통일되고 체계적인 품질 필터링 및 Temporal Alignment를 거쳤습니다. InternW0-Δ는 이 Heterogeneous Corpus에서 Pretraining된 후, Post-training을 통해 Target Embodiment 및 Tasks에 적응됩니다.
실험 결과, InternW0-Δ는 다양한 Simulation Benchmarks 및 Real-Robot Platforms에서 Baseline 대비 우수한 성능을 보였습니다. LIBERO-Plus에서 InternW0-Δ는 92.8%의 Overall Success Rate를 달성하여 기존 최고 성능인 Qwen-RobotManip-Context (91.4%)를 1.4%p 앞섰습니다. 특히 Robot Perturbations 조건에서 91.1%를 달성하며 이전 최고 기록인 87.4%를 능가했습니다. RoboTwin 2.0의 Clean2Random 프로토콜에서는 71.9%의 Success Rate를 기록하여 Qwen-RobotManip-Context (69.4%)보다 2.5%p 높았으며, Overall Score는 81.0%를 달성했습니다. EBench에서는 66.0점의 최고 Overall Score를 기록했으며, 특히 Long Horizon Tasks에서 49.4%의 Success Rate와 76.5점의 Score를 달성했습니다. RoboDojo에서는 23.9%의 Average Success Rate와 30.77점의 Overall Score를 기록하여 기존 WAM들 중 가장 강력한 성능을 보였습니다. Real-Robot Experiments에서도 Pretraining이 Toast bread와 Luminol reaction Task에서 Success Rate를 각각 20%에서 95%, 0%에서 95%로 크게 향상시키는 것을 확인했습니다.
4. Conclusion & Impact (결론 및 시사점)
본 연구는 Pretrained Visual Dynamics, Task-conditioned Scene Semantics, 그리고 Robot Action 생성을 Directed Mixture-of-Transformers Architecture 내에서 결합하여 Action-relevant한 Dynamic Representations을 학습하는 InternW0-Δ를 제안합니다. Causal Imprint와 4D-aware Distillation과 같은 메커니즘을 통해 미래 예측 정보를 Inference 시 미래 Video Rollout 없이 Action 생성에 직접 활용할 수 있도록 한 것이 핵심입니다. 이 연구는 20,000시간 이상의 대규모 Heterogeneous Data를 기반으로 한 확장 가능한 Data, Training, Deployment Recipe를 제시하며, Canonical State 및 Action Representation, 체계적인 품질 필터링, 그리고 Temporal Alignment를 통해 이기종 Data에 대한 Pretraining과 Target Embodiment에 대한 Post-training을 가능하게 했습니다.
InternW0-Δ의 우수한 성능은 다양한 Simulation Benchmarks 및 Real-Robot Platforms에서 입증되었으며, 이는 Gripper-based 및 Dexterous-hand Manipulation을 포함한 여러 Embodiment 및 Control Interface에 대한 적응 능력을 보여줍니다 [Figure 10]. 이 연구는 Embodied Intelligence 및 Physical AI 분야의 발전을 가속화할 것으로 기대됩니다. 특히, 미래 예측 지식을 Inference 시 비용 없이 Action 생성에 활용하는 효율적인 접근 방식은 로봇 정책 학습의 실용성과 성능을 동시에 향상시키는 데 중요한 시사점을 제공합니다.
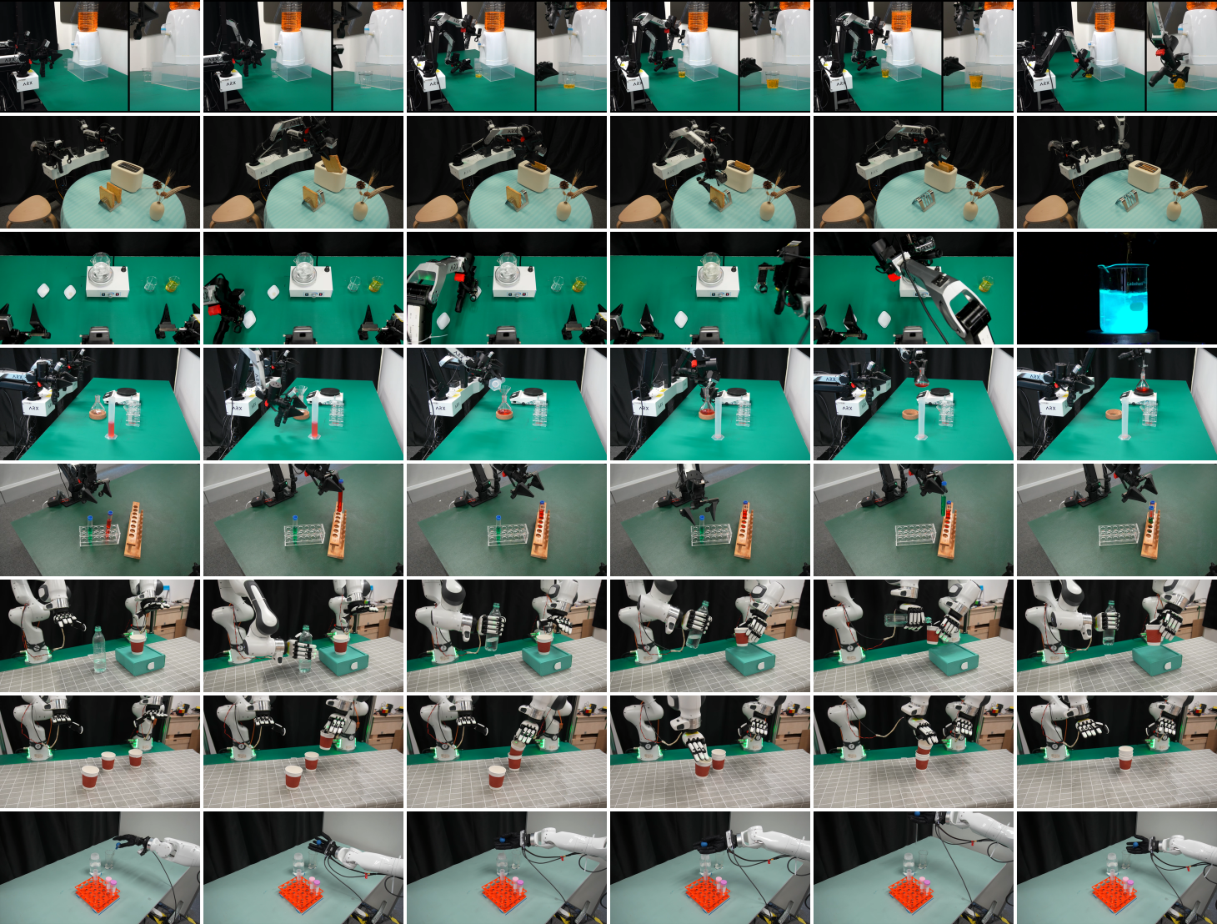
Figure 10 — 실제 로봇 태스크 실행 예시
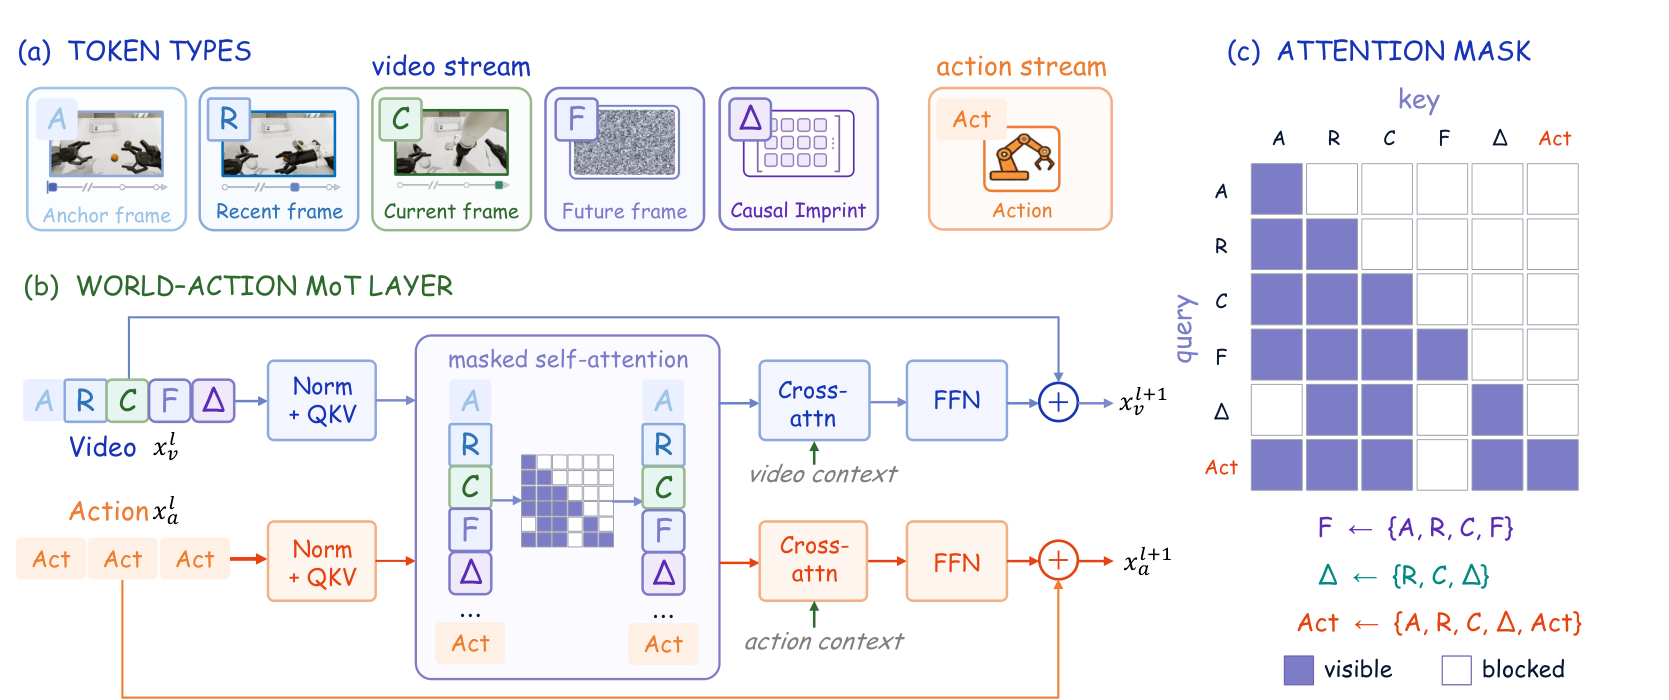
Figure 3 — World-Action MoT 레이어 및 어텐션 마스크
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] GigaWorld-Policy-0.5: A Faster and Stronger WAM Empowered by AutoResearch
- [논문리뷰] ImageWAM: Do World Action Models Really Need Video Generation, or Just Image Editing?
- [논문리뷰] LaWAM: Latent World Action Models for Efficient Dynamics-Aware Robot Policies
- [논문리뷰] Light-WAM: Efficient World Action Models with State-Fusion Action Decoding
- [논문리뷰] VLA-Precision: Asymmetric Co-Bootstrapping for Efficient Real-World Online RL of Vision-Language-Action Models
Review 의 다른글
- 이전글 [논문리뷰] IndicBankBench: Evaluating Safety and Reliability of Language Model Assistants in Indian Retail Banking
- 현재글 : [논문리뷰] InternW0-Δ: A World Action Model Bridging Predictive Dynamics and Actions with 20K+ Hours of Open Data
- 다음글 [논문리뷰] Jev in the Wild: A Data-Driven Analysis of the Jev Model's Functionality, Applications and Ecosystem
댓글