[논문리뷰] More Methods, Better Agents? A Reality Check on Self-Distillation in Agentic Reinforcement Learning
링크: 논문 PDF로 바로 열기
저자: Linhao Zhong, Bozhen Fang, et al.
키워: Self-Distillation, Agentic Reinforcement Learning, Benchmark, Training Stability, Computational Cost, LLM Agents, GRPO
1. Key Terms & Definitions (핵심 용어 및 정의)
- Self-Distillation (SD): Agentic Reinforcement Learning (RL)에서 teacher branch가 training-only privileged information을 활용하여 student-generated trajectories에 denser supervision을 제공하는 기법입니다.
- Agentic Reinforcement Learning (Agentic RL): Large Language Model (LLM) agents가 순차적인 actions과 observations를 통해 환경과 상호작용하고, task-level feedback으로부터 학습하는 강화 학습 패러다임입니다.
- GRPO (Group-Normalized Proximal Policy Optimization): Outcome-based RL의 강력한 baseline으로, 본 연구의 비교 기준으로 사용됩니다.
- Validation AUC (Area Under the Curve): Training stability와 progress를 평가하는 지표로, validation curve 아래 영역을 training-step horizon으로 정규화하여 계산한 값입니다.
- Computational Cost: 각 method를 학습시키는 데 필요한 자원, 특히 H800 GPU-hours로 측정되는 compute time을 의미하며, method의 practical feasibility를 판단하는 데 중요합니다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
Agentic Reinforcement Learning 분야에서 self-distillation methods가 빠르게 증가하고 있지만, 이들 간의 성능을 공정하고 체계적으로 비교할 수 있는 independent benchmark가 부족하다는 점이 본 연구의 핵심 문제입니다. 기존 연구들은 종종 published baseline scores를 재사용하여 상이한 실험 조건으로 인한 차이를 방법론적 발전으로 오인하게 하고, 동시대 method들 간의 직접적인 비교는 거의 이루어지지 않습니다. 또한, training stability와 computational cost에 대한 체계적인 검토가 미흡하여, 각 method의 실제 강점과 약점을 파악하고 어떤 아이디어를 발전시켜야 할지 결정하기 어렵습니다. [Figure 1]에서 볼 수 있듯이, 새로운 method의 확산 속도가 이를 뒷받침할 비교 가능한 증거를 앞지르고 있는 상황입니다. 이러한 한계점은 costly agent training 환경에서 공통된 비교 기준의 필요성을 더욱 증대시키며, 객관적인 평가를 통해 신뢰할 수 있고 cost-effective한 agent training을 위한 기반을 마련해야 합니다.
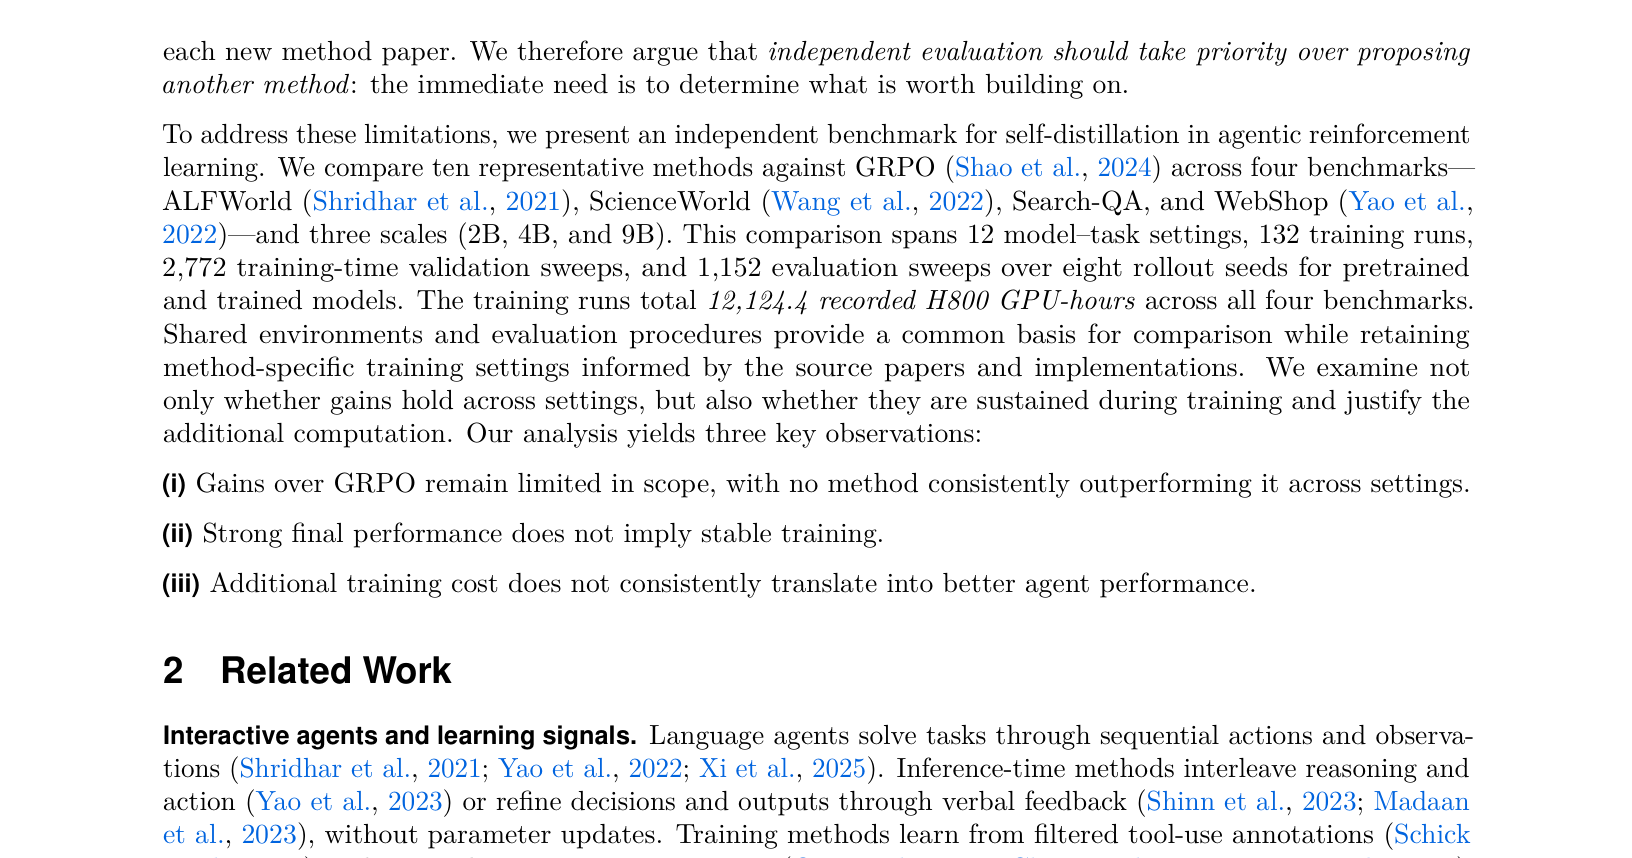
Figure 1 — Self-distillation 연구의 한계점과 본 벤치마크의 필요성 및 구성 요소를 시각적으로 설명하는 핵심 개요 다이어그램입니다.
3. Method & Key Results (제안 방법론 및 핵심 결과)
본 연구는 이러한 문제를 해결하기 위해, GRPO를 baseline으로 하여 10개의 대표적인 self-distillation methods를 비교하는 독립적인 benchmark를 제안합니다. 비교는 ALFWorld, ScienceWorld, Search-QA, WebShop의 4가지 벤치마크와 Qwen3.5-2B, 4B, 9B의 3가지 모델 스케일에 걸쳐 수행되었습니다. 총 132회의 training runs이 진행되었으며, 12,124.4 H800 GPU-hours가 기록되었고, pretrained backbones 및 모든 trained methods에 대해 8개의 rollout seeds로 반복 평가를 수행했습니다. 평가 지표는 final task performance 외에 training progress, stability, 그리고 measured computational cost를 포함했습니다.
주요 정량적 결과는 다음과 같습니다:
- (i) Gains over GRPO remain limited in scope: 연구 결과, 어떤 method도 settings 전반에 걸쳐 GRPO를 일관되게 능가하지 못했습니다. PCSD (평균 54.26, GRPO 대비 +4.58 points)와 AgentOPSD (평균 51.34, GRPO 대비 +1.66 points)만이 GRPO의 twelve-setting 평균 49.68을 초과했습니다. [Table 2]와 [Table 3]은 각 벤치마크에서의 상세 성능을 보여줍니다.
- (ii) Strong final performance does not imply stable training: 예를 들어, AgentOPSD는 4B ALFWorld에서 step 35에 60.0% validation success를 달성했지만, step 45-70 사이에는 4.3% 이하로 떨어졌다가 step 100에 79.3%로 회복하는 등 불안정한 training 궤적을 보였습니다. [Figure S1 (a)]와 [Figure 2]는 strong final result가 안정적인 training process를 의미하지 않음을 명확히 보여줍니다.
- (iii) Additional training cost does not consistently translate into better performance: 120개 비교 중 112개의 method가 GRPO보다 더 많은 net training time을 요구했으며, 이 중 58개는 더 낮은 performance를 기록했습니다. PCSD와 AgentOPSD는 GRPO 대비 평균 training time 비율이 각각 1.17배 및 1.19배였음에도 최종 performance에서만 우위를 보였습니다. [Figure 3]은 final performance와 training time 간의 관계를 시각적으로 제시하며, 추가적인 training effort가 항상 더 높은 performance로 이어지지 않음을 보여줍니다.
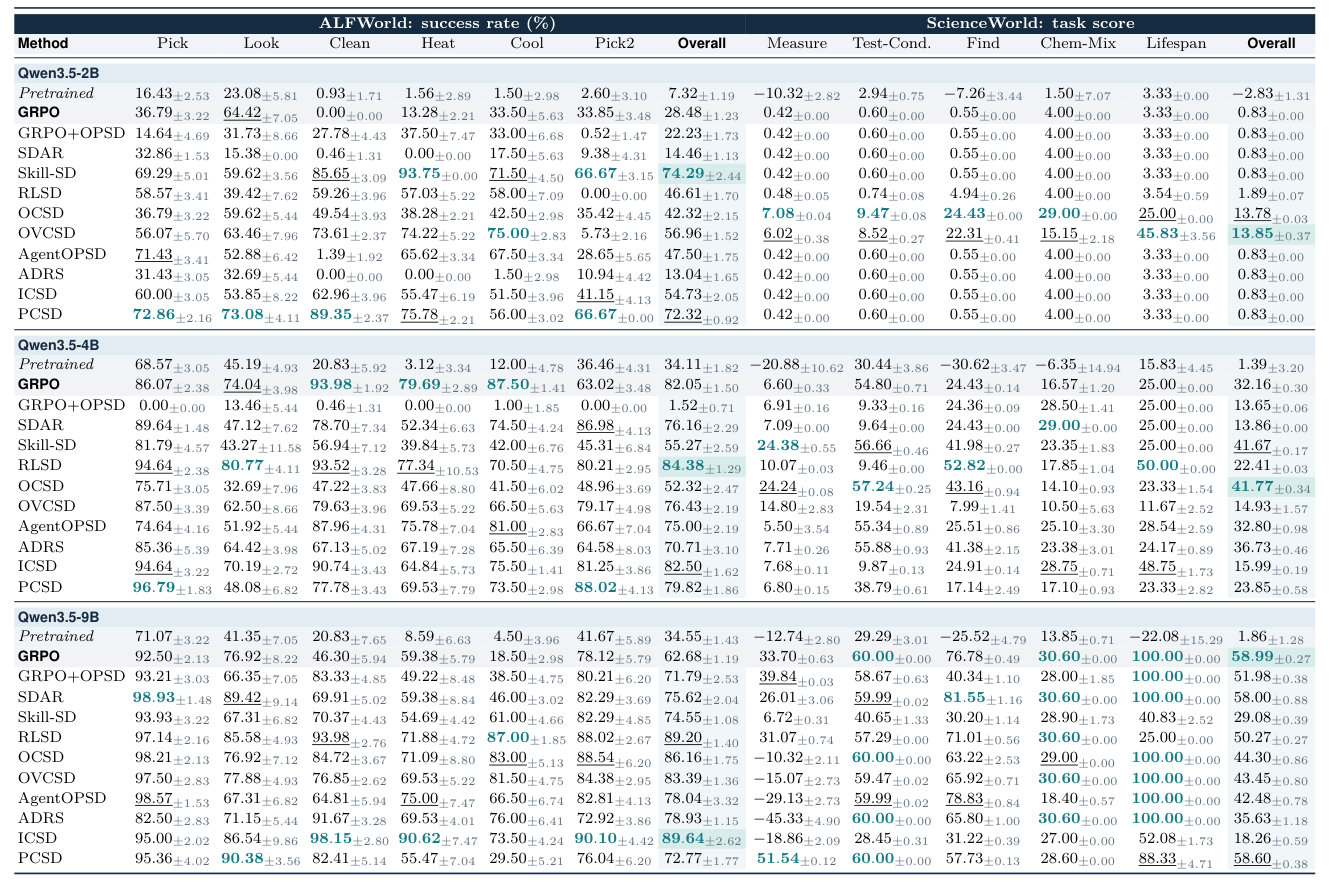
Table 2 — ALFWorld 및 ScienceWorld 벤치마크에서 pretrained 모델과 11가지 training method의 성능을 비교하는 주요 정량적 결과 테이블입니다.
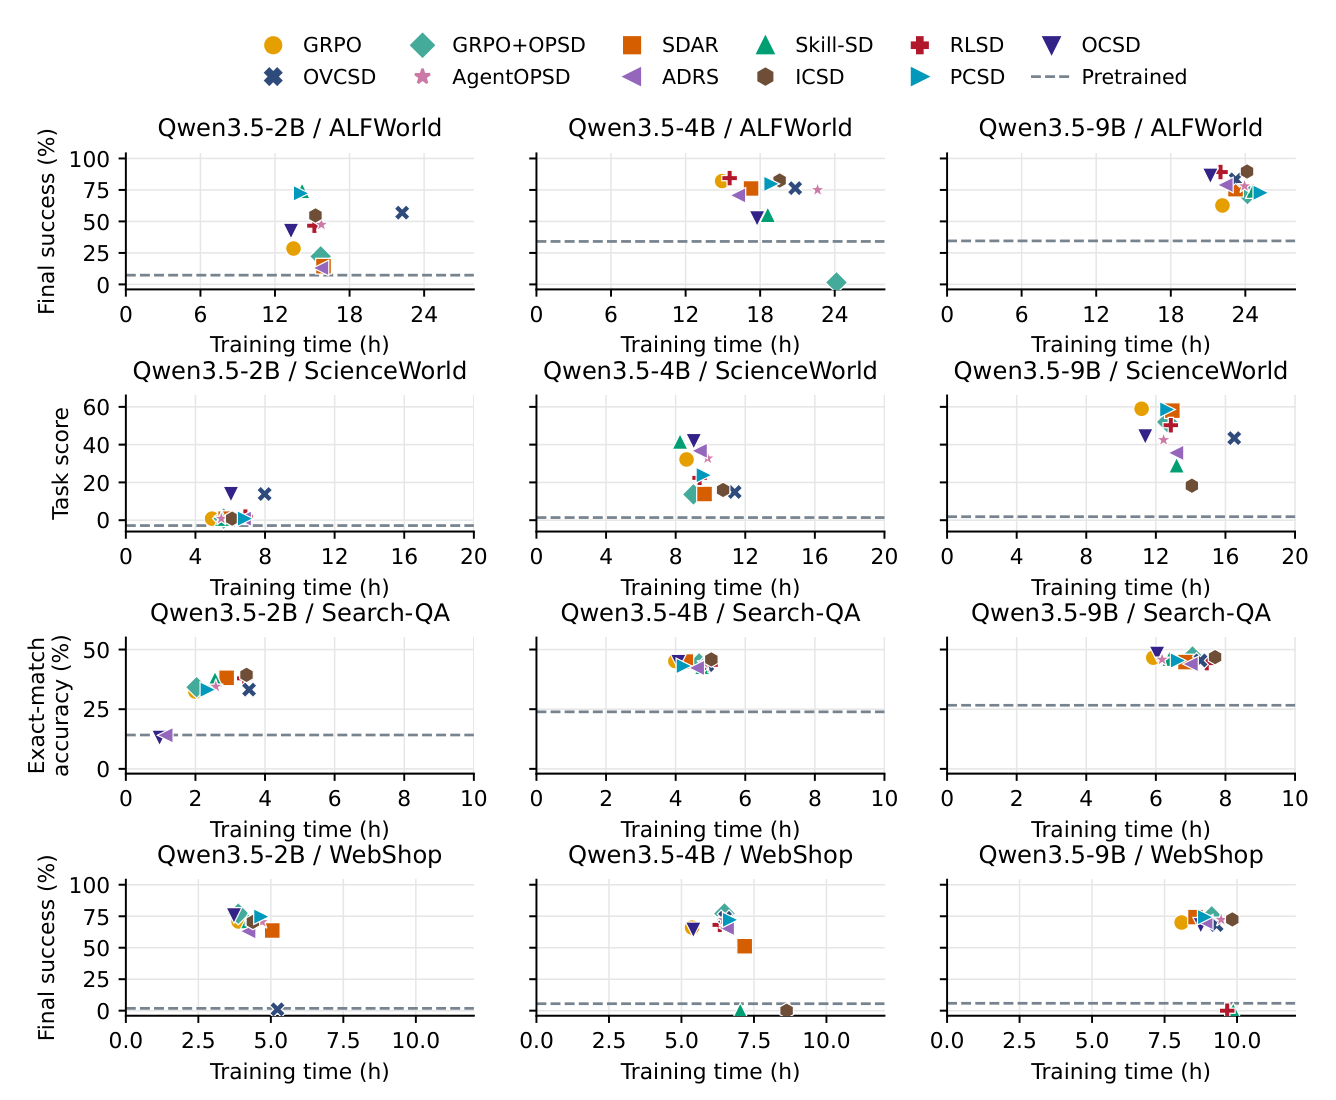
Figure 3 — 12가지 model-task 설정에서 최종 성능과 training time 간의 관계를 보여주는 그래프로, 추가 compute cost가 항상 성능 향상으로 이어지지 않음을 시사하는 핵심 결과입니다.
4. Conclusion & Impact (결론 및 시사점)
본 연구는 self-distillation method들의 이점이 setting-dependent하며, 어떤 method도 settings 전반에 걸쳐 GRPO를 일관되게 능가하지 못한다는 결론을 내립니다. 또한, 강력한 최종 performance가 불안정한 training을 숨길 수 있으며, 추가적인 computational cost가 항상 더 나은 performance로 이어지지는 않는다는 점을 확인했습니다. 이러한 결과는 agent training 분야의 발전을 평가할 때 gains의 폭, 학습의 안정성, 그리고 개선의 비용을 종합적으로 고려해야 함을 시사합니다. 본 연구는 이러한 포괄적인 benchmark를 통해 연구자들이 강력한 baselines를 선택하고, 미해결된 training challenges를 식별하며, 궁극적으로 reliable하고 cost-effective한 agent training을 향한 연구를 진전시키는 데 중요한 가이드라인을 제공할 것입니다. 이는 algorithmic innovation과 더불어 체계적인 평가가 학계 및 산업계에 필수적인 가치로 인식되어야 함을 강조합니다.
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] LLMs4All: A Review on Large Language Models for Research and Applications in Academic Disciplines
- [논문리뷰] WorldCast: Exploring Intelligent Visual Generation in World State Prediction
- [논문리뷰] Waypoint-OPD: Transferring RL-Induced Policy Shifts via Gated On-Policy Distillation
- [논문리뷰] Virtual Head Attention
- [논문리뷰] VLA-Δ: Learning Physical State Transition for Vision-Language-Action Models
Review 의 다른글
- 이전글 [논문리뷰] Many Right Answers, One Training Example: Removing Responder Noise from GRPO for LLM Recommenders
- 현재글 : [논문리뷰] More Methods, Better Agents? A Reality Check on Self-Distillation in Agentic Reinforcement Learning
- 다음글 [논문리뷰] Player-1: Learning to Play from Synthetic Experience
댓글