[논문리뷰] LongLive-Plug: Once-for-All Distillation for Video Generation
링크: 논문 PDF로 바로 열기
저자: Shuai Yang, Luozhou Wang, Wei Huang, et al.
1. Key Terms & Definitions (핵심 용어 및 정의)
- LongLive-Plug: 비디오 생성 모델에서 재사용 가능한(reusable) 학습된 역량(capabilities)을 LoRA 형태로 추출하여 다양한 downstream 모델에 training-free하게 plug-and-play 방식으로 배포하는 once-for-all distillation 프레임워크입니다.
- Functional LoRAs: LongLive-Plug 프레임워크에서 특정 기능을 수행하도록 학습된 LoRA 모듈을 지칭하며, CFG distillation, few-step distillation, long-context distillation 세 가지 역량을 포함합니다.
- Classifier-Free Guidance (CFG) Distillation: 두 번의 모델 평가(conditional 및 unconditional)를 하나의 조건부 평가로 통합하여 샘플링 속도를 높이면서도 guidance strength에 대한 연속적인 제어(continuous control)를 유지하는 기법입니다.
- Few-Step Distillation: Distribution Matching Distillation (DMD2)를 활용하여 diffusion model의 샘플링 스텝 수를 획기적으로 줄여(예: 4단계) 추론 속도를 가속화하는 기법입니다.
- Long-Context Distillation: causal autoregressive (AR) 추론을 지원하는 모델에서 발생하는 누적된 오류(accumulated errors)를 수정하여 긴 비디오 생성의 품질을 향상시키는 기법입니다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
비디오 diffusion model은 점차 다양한 downstream task를 위한 specialized model로 발전하고 있으며, 이러한 과정에서 샘플링 가속화나 long-video 생성 개선을 위한 distillation 단계가 필수적으로 요구됩니다. 그러나 이러한 distillation 단계는 새로운 specialized model마다 반복적으로 수행되어야 하며, 이는 데이터 준비, teacher supervision, 최적화 등 상당한 비용을 발생시킵니다. 기존 few-step distillation 방법론들은 CFG와 few-step 생성을 jointly distill하여 학습 시 고정된 guidance scale에 묶이는 한계가 있었고, 이로 인해 downstream task의 다양한 guidance 선호도를 충족시키지 못했습니다. 또한, functional LoRA의 transfer 능력에 대한 이해가 부족하여, 어떤 training 설정이 base checkpoint를 넘어 재사용 가능한 가속화를 가능하게 하는지에 대한 질문이 남아있었습니다.
3. Method & Key Results (제안 방법론 및 핵심 결과)
본 논문은 반복적인 distillation 비용을 줄이고자 LongLive-Plug라는 once-for-all distillation 프레임워크를 제안합니다. 이 프레임워크는 base model에서 재사용 가능한 세 가지 functional LoRAs(CFG distillation, few-step distillation, long-context distillation)를 학습하고, 이들을 training-free plug-and-play 방식으로 호환 가능한 downstream model에 배포합니다.
CFG Distillation은 teacher model의 guided prediction $v_{\mathrm{cfg}}^{(w)}$를 고정된 target으로 간주하고, CFG LoRA $\phi_{\mathrm{cfg}}$만을 학습하여 하나의 conditional evaluation으로 single-pass guidance를 가능하게 합니다. 특히, inference weight $\lambda_{\mathrm{cfg}}$를 조정함으로써 학습 시 고정된 guidance scale $w_{\mathrm{train}}$에도 불구하고 guidance strength를 조절하는 "guidance dial" 역할을 수행합니다 [Figure 1]. 이는 $\lambda_{\mathrm{cfg}}(w_{\mathrm{train}}-1)$에 따라 $\widetilde{w}$가 변화하는 근사적으로 선형적인 관계를 통해 이루어집니다.
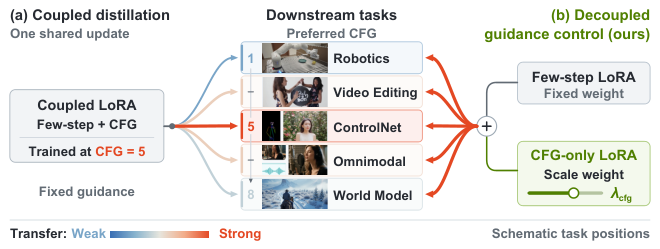
Figure 1 — 디커플링된 가이던스 제어
Decoupled Guidance Control을 위해 CFG-only LoRA와 few-step LoRA를 별도로 학습시켜, few-step LoRA의 weight $\lambda_{\mathrm{step}}$을 고정한 채로 CFG LoRA의 weight $\lambda_{\mathrm{cfg}}$만 조절하여 guidance를 제어할 수 있도록 합니다 [Figure 1]. 이 두 LoRA의 업데이트는 각 downstream layer에 독립적으로 더해져($\widetilde{W}{\ell}^{(\tau)}=W{\ell}^{(\tau)}+\lambda_{\mathrm{step}}\Delta W_{\ell,\mathrm{step}}+\lambda_{\mathrm{cfg}}\Delta W_{\ell,\mathrm{cfg}}$) downstream training 없이도 task-specific module들을 보존합니다.
Transfer-Oriented Design을 위해 저자들은 adapter rank와 distillation data의 중요성을 강조합니다. 실험 결과, rank를 16에서 128로 두 배씩 증가시킬 때 FVD가 21% 개선되어, 더 높은 rank가 downstream transfer 품질을 향상시킴을 보였습니다. 또한, 넓은 범위의 T2V 프롬프트(broad T2V prompts)를 사용하여 distillation 데이터를 다양화할 때 FVD가 12% 개선되어, prompt diversity가 transfer 품질에 긍정적인 영향을 미침을 확인했습니다.
Long-Context Distillation은 causal AR base model에 $\phi_{\mathrm{long}}$ LoRA를 학습시켜 긴 비디오 생성 중 발생하는 누적 오류를 수정합니다. Streaming Long Tuning을 사용하여 student model이 자신의 생성된 이력(generated history)으로부터 새로운 클립을 생성하고, teacher가 각 새 클립에 대해 distribution matching distillation (DMD) supervision을 제공하는 방식으로 이루어집니다.
핵심 결과로, LongLive-Plug는 SCOPE 벤치마크에서 FVD를 805.5에서 478.7로 대폭 감소시켜, SCOPE-specific distillation(502.1)과 유사하거나 더 우수한 성능을 달성했습니다 [Table 1]. Wan2.2-Fun-5B-Control 벤치마크에서는 naive four-step sampling 대비 모든 6가지 metric에서 개선을 보였으며, 특히 depth si-RMSE는 2.135에서 1.641로, DOVER는 8.90에서 10.11로 향상되었습니다 [Table 2]. 이는 downstream training 없이도 four-step generation에서 높은 visual quality를 유지함을 보여줍니다 [Figure 3]. LongLive-Plug는 Wan2.1-14B, Wan2.2-TI2V-5B, MiniMax-H3 등 3개 backbone family와 8개 task category에 걸쳐 54개의 downstream model에 training-free deployment를 성공적으로 검증했습니다. 또한, long-context LoRA를 ReWorld 및 Matrix-Game 3.0 world model에 전이했을 때, ReWorld에서는 64초 길이의 rollout에서 VBench 7개 차원 평균 점수가 73.51에서 75.77로 증가했으며, Matrix-Game 3.0에서는 task-specific distillation과 유사한 84.34의 총점을 달성했습니다 [Table 3]. 이러한 결과들은 LongLive-Plug가 재사용 가능한 가속화 및 long-context error correction 기능을 제공함을 입증합니다.
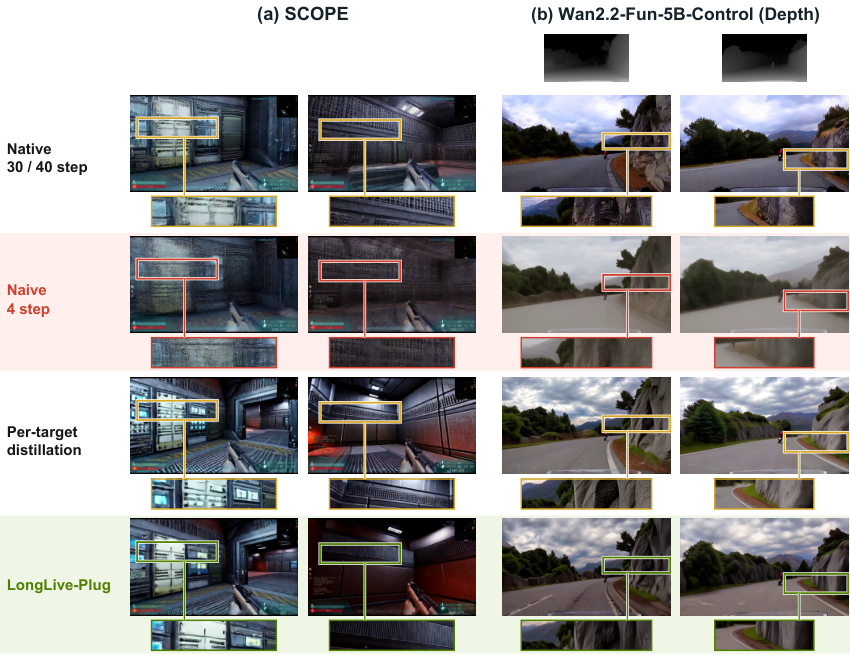
Figure 3 — 매칭된 전이 비교 키프레임
4. Conclusion & Impact (결론 및 시사점)
LongLive-Plug는 CFG, few-step sampling, long-context error correction과 같은 역량들을 backbone family별로 단 한 번만 학습된 reusable LoRA로 제공합니다. 이 접근 방식은 호환 가능한 downstream model에 training-free plug-and-play 방식으로 전이될 수 있으며, guidance strength 조절 기능도 함께 제공합니다. 실험을 통해 LongLive-Plug는 효과적인 추론 가속화와 long-video 품질 개선을 다양한 task에서 입증했으며, 이는 per-target distillation의 필요성을 크게 줄여줍니다. 이 연구는 비디오 생성 모델 개발의 효율성을 혁신하여, specialized model의 배포 비용을 절감하고, 학계 및 산업계에서 diffusion model의 활용 범위를 확장하는 데 기여할 것입니다.
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] Video DeltaNet: A Video-Native Hybrid Attention for Livestream Video Generation
- [논문리뷰] Warp-as-History: Generalizable Camera-Controlled Video Generation from One Training Video
- [논문리뷰] Streaming Autoregressive Video Generation via Diagonal Distillation
- [논문리뷰] Helios: Real Real-Time Long Video Generation Model
- [논문리뷰] SALAD: Achieve High-Sparsity Attention via Efficient Linear Attention Tuning for Video Diffusion Transformer
Review 의 다른글
- 이전글 [논문리뷰] LongCat-DeepResearch Technical Report
- 현재글 : [논문리뷰] LongLive-Plug: Once-for-All Distillation for Video Generation
- 다음글 [논문리뷰] MaLiang-Harness: A Programmable Path to Image and Video Generation
댓글