[논문리뷰] AnyGoal: On World Model Generalization Beyond Expert Rollouts
링크: 논문 PDF로 바로 열기
저자: Heejeong Nam, Divyat Mahajan, Quentin Le Lidec, Randall Balestriero, David Klindt
1. Key Terms & Definitions (핵심 용어 및 정의)
- World Model: 환경의 Dynamics를 학습하여 에이전트가 Actions를 계획하고 Simulate할 수 있도록 하는 모델입니다.
- Compositional Generalization: Training Data에서 Joint Combinations가 충분히 Cover되지 않은 경우에도, Familiar Components (State Factors, Actions)를 재조합하여 Unseen Configurations에 대해 Generalize할 수 있는 모델의 능력입니다.
- Goal-Shift: Individually Familiar한 State와 Action Factor들의 새로운 Combinations를 유발하는 Task Objective의 변화로, Training Data의 Under-covered Regions를 Target합니다.
- Combinatorial Gap: Marginal Training Supports의 Cartesian Product 내에 존재하지만, Training Joint State-Action Support에는 없는 Regions로, Novel하지만 Compositionally In-distribution인 시나리오를 나타냅니다.
- Action Sensitivity: Interventional Action Inputs에 대한 모델의 Predicted Representation 변화 정도를 측정하는 지표로, Behavior Policy Shortcuts에 대한 의존도를 진단하는 데 사용됩니다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
본 논문은 현재 World Model들이 Expert Rollouts에서 관찰된 특정 State-Action Combinations를 넘어 새로운 Planning Tasks에 대한 Generalize 능력이 부족하다는 핵심 문제를 제기합니다. 기존 연구들은 Data Coverage, Dynamics Generalization, 그리고 Downstream Planning Performance 간의 관계를 충분히 탐색하지 못했습니다. 특히, Off-distribution Evaluation이 종종 Training Support 범위를 벗어나는 새로운 Factors를 도입하는 반면, 본 연구의 목표인 Reusable Dynamics의 Generalization 테스트와는 차이가 있습니다. Goal-directed Policies로 수집된 Offline Datasets는 강한 State-Action Correlations를 유발하여, 모델이 진정한 Action-conditioned Dynamics 대신 Behavior Policy Shortcuts를 학습하게 되는 한계를 보입니다. 이러한 불완전한 Data Coverage 환경에서 Generalization을 연구하는 것은 Data Scale만으로 해결될 수 없는 중요한 도전 과제입니다.
3. Method & Key Results (제안 방법론 및 핵심 결과)
저자들은 World Model이 학습된 Goal-directed Trajectories를 넘어 Generalize하는지 평가하기 위한 벤치마크인 AnyGoal을 제안합니다 [Figure 2, cite: 1]. AnyGoal은 TwoRoom, Push-T, DMC Manipulator Insert-Peg, OGBench Cube 등 널리 사용되는 네 가지 World Model Environments에서 파생된 Goal-shifted Task Variants로 구성됩니다. 이 벤치마크는 State Factors, Actions 및 Task-relevant Factors의 Observed Marginal Support를 유지하되, Training Behavior Distribution에 의해 유도된 Joint Combinations를 변경하여 Combinatorial Gap을 Target하도록 설계되었습니다. 각 Task Variant는 Factor-wise Support Checks (Range, Mahalanobis, KDE)를 통과하도록 신중하게 검증되어, Test Distribution이 Marginal하게는 In-distribution이지만 Jointly는 Novel한 시나리오를 보장합니다. 모델은 Rollout Prediction Error (MSE)와 Downstream MPC Planning Success Rate의 두 가지 주요 Metric으로 평가되며, Visual Representation Failure와 Dynamics Learning Failure를 분리하기 위해 Oracle-State Predictors도 함께 분석됩니다.
실험 결과, 현재 World Model들은 개별 State Factors와 Actions가 Training Support 내에 있음에도 불구하고 Goal-shifted Recombinations에서 일관된 성능 저하를 보였습니다. 특히, Oracle-State Predictors를 사용했을 때, AnyGoal Gap이 Visual Representation Failure만으로 설명될 수 없다는 점이 드러났습니다 [Figure 6, cite: 1]. Free-space variants (예: TR-Route, Avoid-T)에서는 MPC Performance가 유지되거나 향상되었지만, Contact-rich variants에서는 예측 및 Planning 성능이 일관되게 저하되었으며, Rollout Error가 1~3 Order of Magnitude 더 크게 증가했습니다. 이는 정밀한 Object Interaction Dynamics의 Generalization이 더 어렵다는 것을 시사합니다. 또한, End-to-end World Models에서는 Visual Representation 학습 과정에서 발생하는 Observation-level Shifts와 Learning Latent Geometry의 영향으로 추가적인 성능 저하가 관찰되었습니다. Action Sensitivity 분석을 통해, Goal-biased Training Support가 강하게 작용하는 State Regions에서는 Interventional Action에 대한 모델의 Sensitivity가 감소하여, 모델이 Reusable Dynamics 대신 Behavior-Policy Shortcuts에 의존한다는 점이 진단되었습니다 [Figure 9, cite: 1].
4. Conclusion & Impact (결론 및 시사점)
본 논문은 AnyGoal 벤치마크를 도입하여 World Model들이 Familiar States and Actions를 재조합하여 새로운 Behavioral Goals에 Generalize하는 능력에 대한 체계적인 평가를 수행했습니다. 실험을 통해 다양한 모델에서 Goal-Shift Generalization이 어려우며, 이러한 실패는 Representation, Dynamics Prediction, Task Structure 및 Evaluation Metric 간의 복잡한 상호작용으로 인해 발생함을 규명했습니다. AnyGoal은 World Model 평가를 Compositional Generalization 개념과 연결하며, Marginal Training Supports의 Product 내에서 Novel Joint State-Action Combinations에 대한 예측 능력을 요구하는, 합리적이지만 아직 해결되지 않은 중요한 과제를 제시합니다. 이론적 분석은 Global Coverage가 비현실적임을 지적하고, 대신 World Model이 Behavior-Policy Shortcuts 대신 Action-conditioned Mechanisms을 식별할 수 있도록 Local Mechanism Inputs에 대한 Coverage와 적절한 Objective 또는 Architecture가 필요함을 시사합니다. 궁극적으로 AnyGoal은 Goal-induced Recombination을 Failure Mode로 분리하여, Expert Rollouts를 넘어 Reusable Dynamics를 학습하는 World Model 연구 발전을 위한 통제된 기반을 제공합니다.
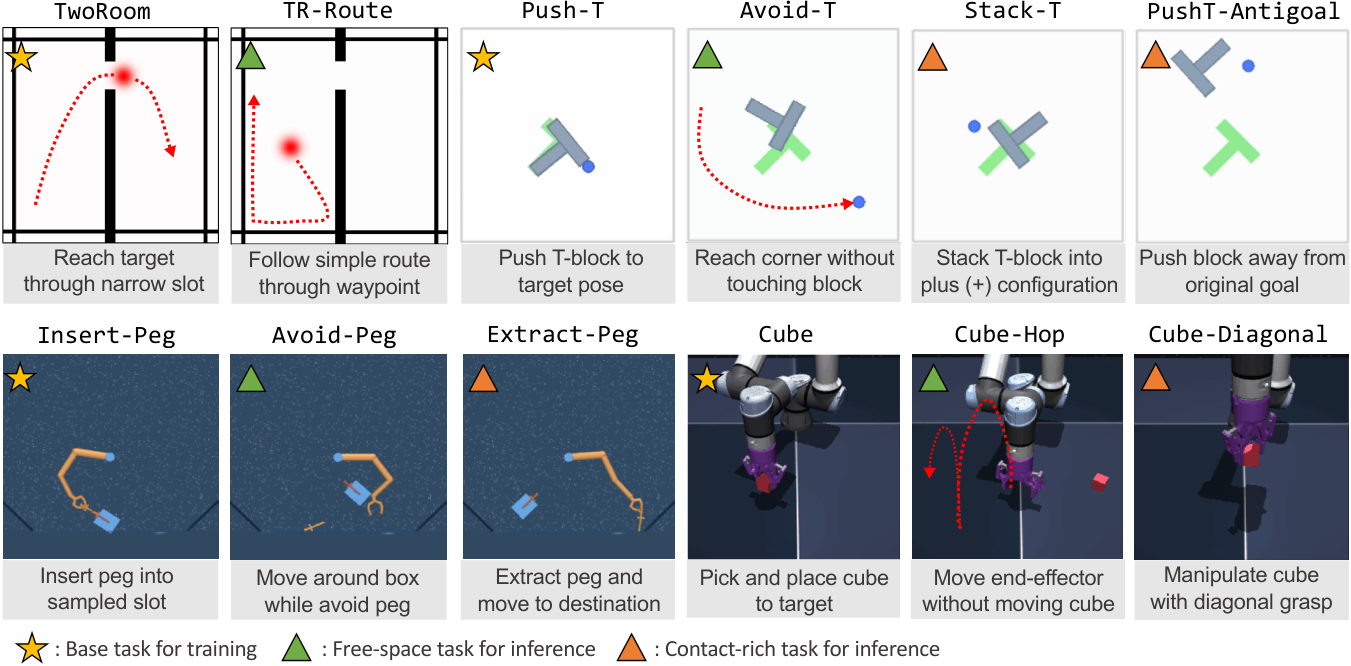
Figure 2 — AnyGoal 벤치마크 개요
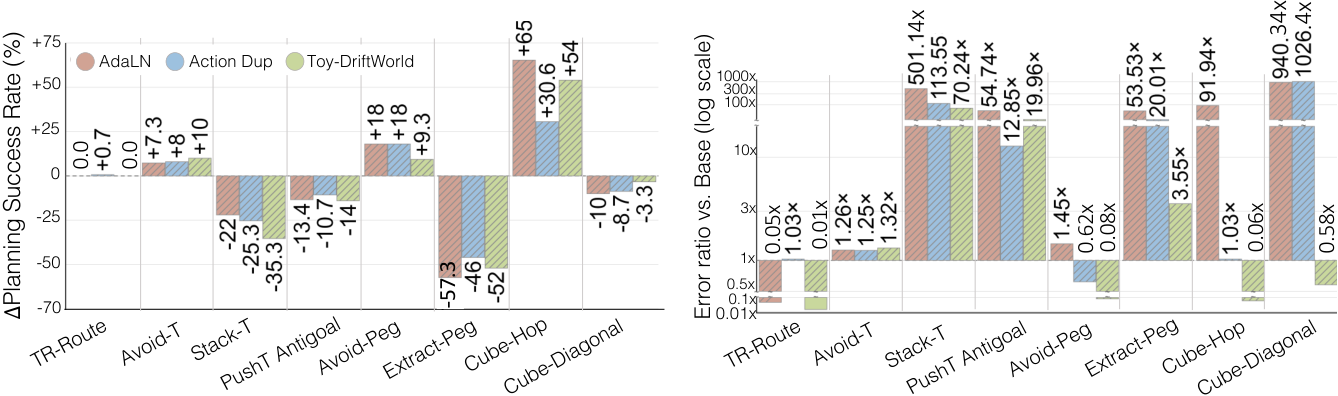
Figure 6 — Oracle-state 예측기 결과
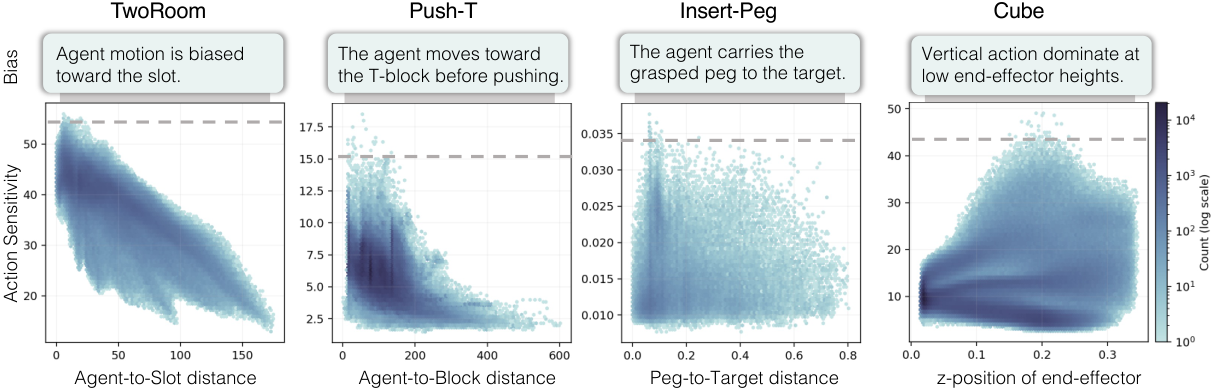
Figure 9 — 행동 편향에 따른 Action Sensitivity
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] Training Object Permanence in World Models
- [논문리뷰] PlayWorld: Benchmarking World Models with Agent Players over Long-Horizon Objectives
- [논문리뷰] Apple-π: Benchmarking Thinking with Video Towards Law-Grounded Physical Intelligence
- [논문리뷰] WorldOlympiad: Can Your World Model Survive a Triathlon?
- [논문리뷰] OdysseyArena: Benchmarking Large Language Models For Long-Horizon, Active and Inductive Interactions
Review 의 다른글
- 이전글 [논문리뷰] AffordanceWAM: Affordance-Aware Joint World-Action Modeling for Robot Manipulation
- 현재글 : [논문리뷰] AnyGoal: On World Model Generalization Beyond Expert Rollouts
- 다음글 [논문리뷰] BlenderWorld: Benchmarking Visual Agents for 3D Creation from Real-World References
댓글