[논문리뷰] Think Visually Across Space and Time: Grounded Reasoning for Video Segmentation
링크: 논문 PDF로 바로 열기
저자: Junwei Wen, Deshui Miao, Guangming Lu, et al.
1. Key Terms & Definitions (핵심 용어 및 정의)
- Video Reasoning Segmentation (VRS): 모델이 암시적으로 기술된 타겟을 식별하고 해당 픽셀 레벨 마스크 궤적을 예측하며, 답변을 결정하는 공간 관계 및 시간적 이벤트를 해결해야 하는 태스크입니다.
- Video Reference Gap: 언어적 추론과 프레임에 걸쳐 분포된 시각적 증거 사이에 발생하는 불일치로, 어떤 시각적 관찰이 타겟 선택을 지원하고 언제 쿼리된 이벤트가 유효하며 해당 증거가 어디에 나타나는지 불확실하게 만듭니다.
- Temporal Chain of Video Primitives (TCoVP): 쿼리 관련 관찰을 시간 순서에 따른 추론 체인으로 구성하는 시공간적으로 Ground된 Video CoT 형태입니다. 각
Primitive는entity reference,temporal support,timestamped spatial evidence를 연관시키고, 이Chain은 이러한reference들을 언어와 엮어entity가 언제 관련event가 발생하는지,evidence가 어디에 나타나는지에 대한 추론을 안내합니다. - Video Primitive:
id,semantic state,timestamp,bounding box,temporal support,action or relation으로 정의되는 시각적 증거의 단위입니다. 동일한id는entity continuity를 유지합니다. - Chain-aligned Reinforcement Learning:
Structural validity,Temporal alignment,Spatiotemporal grounding,Target primitive accuracy보상 함수를 통해TCoVP Chain생성을 최적화하는reinforcement learning전략입니다.
2. Motivation & Problem Statement (연구 배경 및 문제 정의)
기존 Video Reasoning Segmentation (VRS) 연구는 Chain-of-Thought (CoT) 추론을 사용하여 쿼리에 대한 중간 해석을 명시하지만, 추론 자체를 실제 scene에 ground하는 데 어려움이 있습니다. 특히, linguistic descriptions이 어떤 시각적 관찰이 target choice를 지원하고 언제 그 choice가 쿼리를 만족시키는지 불확실하게 만드는 video reference gap 문제를 해결하지 못합니다 [Figure 1]. 기존 접근 방식들은 latent segmentation tokens나 keyframe selection, geometric prompts를 통해 language와 masks를 연결하지만, contextual evidence와 target을 구분하고, 쿼리된 action과 object의 전체 가시성 기간을 분리하는 데 한계가 있습니다. 이러한 한계로 인해 target과 관련된 action interval을 정확하게 식별하지 못하거나, query된 event가 아닌 다른 event에 초점을 맞춰 잘못된 segmentation 결과를 도출할 수 있습니다 [Figure 1]. 따라서 본 논문은 Video CoT에 explicit spatial and temporal guidance를 제공하여 추론 과정 전반에 걸쳐 visual references를 시간적 chain으로 구성하는 새로운 접근 방식의 필요성을 제기합니다.
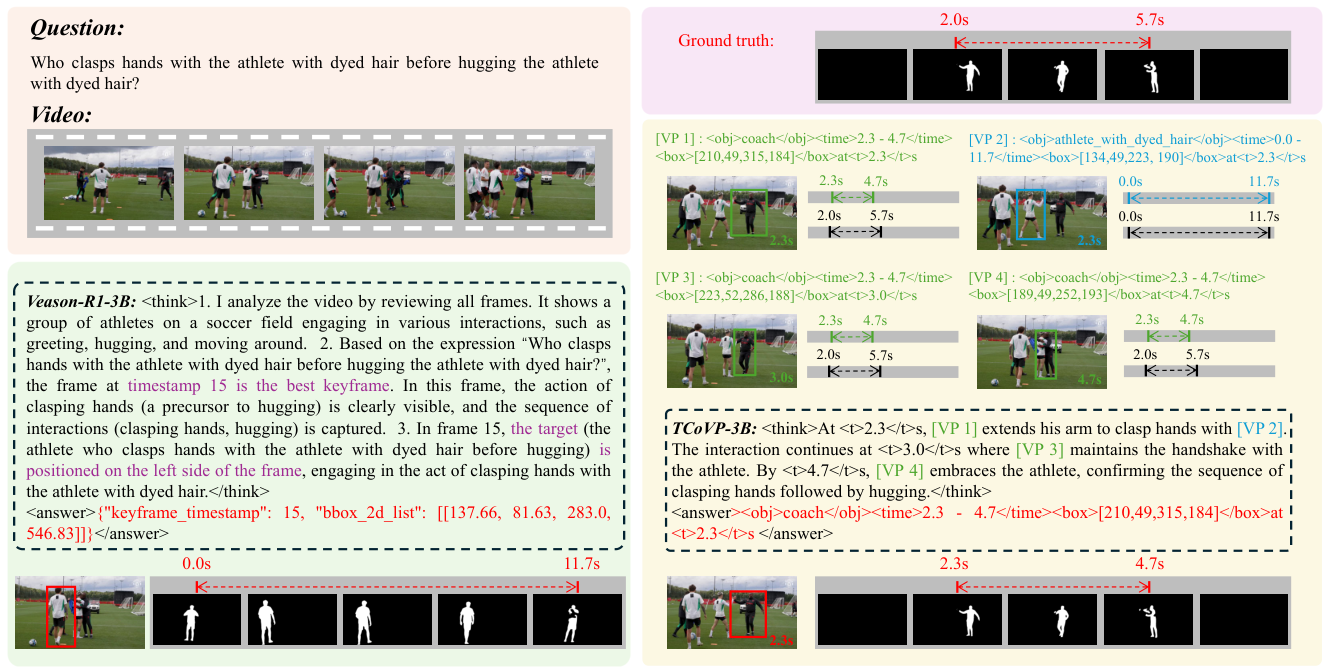
Figure 1 — TCoVP 추론 예시
3. Method & Key Results (제안 방법론 및 핵심 결과)
본 논문은 video reference gap을 해소하기 위해 Temporal Chain of Video Primitives (TCoVP)를 제안합니다. TCoVP는 query-conditioned visual evidence를 timestamped video primitives의 순서화된 시간 chain으로 표현합니다. 각 primitive는 entity reference, temporal span, timestamp, bounding box 및 semantic description을 결합하며, 동일한 identifier를 재사용하여 entity continuity를 유지하고 chronological ordering을 통해 evidence의 시간적 전개를 기록합니다. 이 chain은 <obj>, <time>, <box>, <t> 태그와 natural-language reasoning을 interleave하여 autoregressive decoding이 가능하도록 설계되었습니다. 추론 완료 후, <answer> 블록에서 선택된 target primitives는 mask propagation을 위한 timestamped box prompts를 제공하며, query가 action interval을 지정할 경우 temporal support에 따라 출력을 제한합니다.
TCoVP는 TCoVP-SFT-15k 데이터셋을 활용한 supervised fine-tuning (SFT)과 TCoVP-RL-13k 데이터셋을 활용한 chain-aligned reinforcement learning을 통해 학습됩니다 [Figure 2, 3]. Reinforcement learning 단계에서는 structural validity reward (ℛstr), temporal alignment reward (ℛta), spatiotemporal grounding reward (ℛstg), target primitive accuracy reward (ℛacc)를 포함하는 복합 보상 함수를 사용하여 최적화됩니다. 특히, GroundMoRe 벤치마크에서는 TCoVP-M-4B가 55.37 J&F를 달성하며 기존 VRS baseline인 VideoSEG-O3-4B의 31.96 J&F 대비 23.41%p 이상 크게 향상된 성능을 보였습니다 [Table 1]. 일반 VRS 벤치마크 (Long-RVOS, ReasonVOS, ReVOS, MeViS)에서도 TCoVP는 여러 MLLM backbones에서 VideoSEG-O3-4B를 일관되게 능가하며, Long-RVOS에서 TCoVP-M-4B가 67.4 J&F, ReasonVOS에서 TCoVP-4B가 72.1 J&F를 달성했습니다 [Table 2]. Ablation study 결과, TCoVP는 text-only CoT 대비 macro-average J&F를 57.8에서 62.7로 개선했으며, chain-aligned reinforcement learning과 temporal alignment, spatiotemporal grounding rewards가 각각 성능 향상에 기여함이 입증되었습니다 [Table 3, 4]. Oracle study를 통해 GroundMoRe에서 temporal localization이 spatial grounding보다 주요한 error source임을 밝히고, query-relevant action interval로 mask propagation을 제한하는 것이 중요함을 보여주었습니다 [Table 6].
4. Conclusion & Impact (결론 및 시사점)
본 연구는 Temporal Chain of Video Primitives (TCoVP)를 도입하여 primitive-based visual reasoning을 비디오로 확장하는 새로운 추론 프레임워크를 제안합니다. TCoVP는 query-relevant evidence를 시간 순서로 축적하고, 반복되는 entity identifier를 통해 시간에 걸친 observation을 연결하며, 각 primitive가 explicit temporal support와 spatial grounding을 제공함으로써 중간 추론을 구조화하고 검증 가능하게 만듭니다. language와 primitive를 interleave함으로써 autoregressive MLLMs가 grounded reasoning traces를 생성할 수 있게 하며, 최종 target primitives는 SAM3의 mask propagation을 위한 timestamped bounding-box prompts로 활용됩니다. 이러한 접근 방식은 특히 motion-grounded queries에서 entity continuity와 explicit temporal and spatial references를 유지하는 것의 가치를 입증하며, 여러 backbones와 benchmarks에서 일관된 성능 향상을 가져왔습니다. 이는 video reasoning 분야에서 linguistic inference와 visual evidence 간의 video reference gap을 효과적으로 해소하고, pixel-level video segmentation의 정확성과 신뢰성을 크게 향상시킬 수 있는 중요한 시사점을 제공합니다.
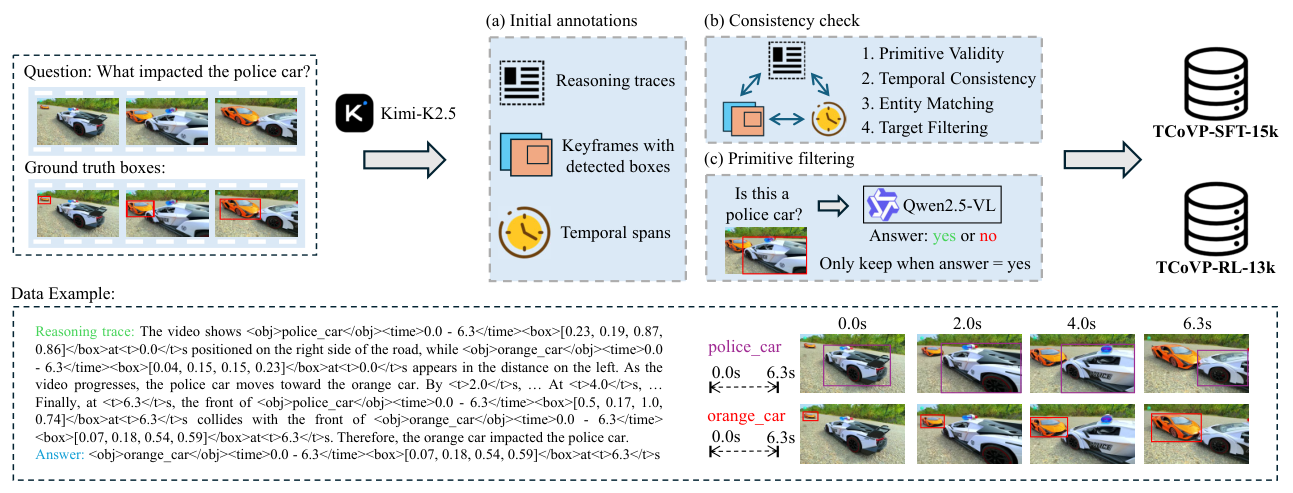
Figure 2 — TCoVP 데이터 구축 파이프라인
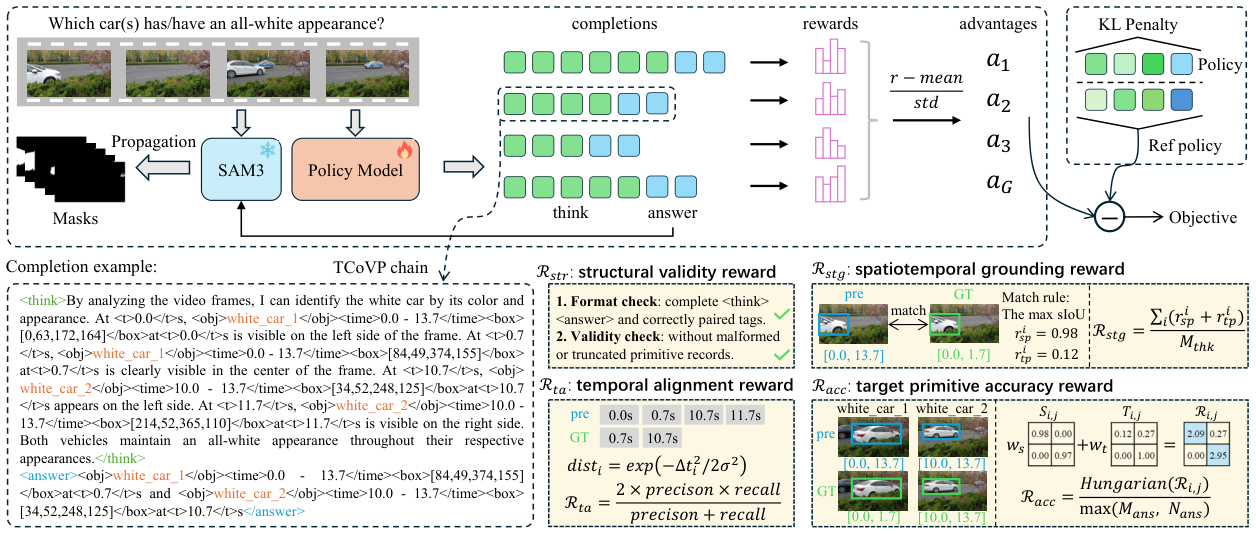
Figure 3 — Chain-aligned 학습 및 마스크 실행
⚠️ 알림: 이 리뷰는 AI로 작성되었습니다.
관련 포스트
- [논문리뷰] Open-o3-Video-v2: Seek, Ground, and Reason with Verifiable Spatio-Temporal Evidence
- [논문리뷰] SpatialASM: Internalizing Active Mentalization for Spatial Reasoning
- [논문리뷰] Inducing Process Supervision from Outcome-Only Reinforcement Learning
- [논문리뷰] Efficient Reasoning Training Does Not Always Harm CoT Faithfulness and Monitorability
- [논문리뷰] OmniSeek: Native Tool Integration for Multi-turn Audio-Visual Reasoning
Review 의 다른글
- 이전글 [논문리뷰] State World Models: Execute the Rules, Generate the Pixels
- 현재글 : [논문리뷰] Think Visually Across Space and Time: Grounded Reasoning for Video Segmentation
- 다음글 [논문리뷰] UniAVC: Unified Audio-Video Creation via Progressive Training and Asymmetric Scheduling
댓글